Build Find open-source tools with concrete interfaces, environments, and setup notes.
Evaluate Browse benchmarks and check observation access, action spaces, and evaluation boundaries.
Watch Explore original video demos in games, simulation, and the physical world.
Original research-team videos, embedded from their source sites. These selected clips illustrate behavior; they are not independent measurements of success. Expand a card for its setting, playback notes, and related work.
Original knowledge-base review label: Compiled from original notes
BibTeX citation
@misc{kb-g05,
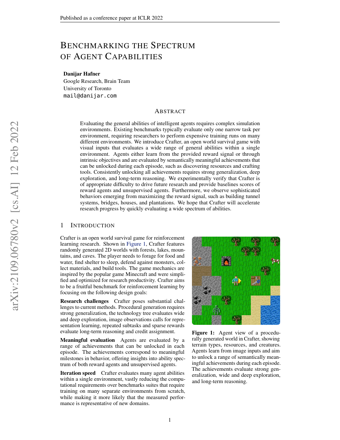
  title = {Mastering diverse control tasks through world models},
  author = {Danijar Hafner and Jurgis Pasukonis and Jimmy Ba and Timothy Lillicrap},
  year = {2025},
  url = {https://www.nature.com/articles/s41586-025-08744-2},
  doi = {10.1038/s41586-025-08744-2}
}
Sources checked 2026-09-14 · Knowledge-base ID G05
PublishedMoo Jin Kim, Karl Pertsch, Siddharth Karamcheti et al.
Unifies vision, language, and robot actions in an open model, with released weights and training tools for adaptation to new tasks.
Vision-language-actionRobot learning
Details & sources
Authors: Moo Jin Kim, Karl Pertsch, Siddharth Karamcheti, Ted Xiao, Ashwin Balakrishna, Suraj Nair, Rafael Rafailov, Ethan P Foster, Pannag R Sanketi, Quan Vuong, Thomas Kollar, Benjamin Burchfiel, Russ Tedrake, Dorsa Sadigh, Sergey Levine, Percy Liang, Chelsea Finn
Publication note: The conference took place in 2024; PMLR proceedings were published in 2025.
BibTeX citation
@misc{openvla,
  title = {OpenVLA: An Open-Source Vision-Language-Action Model},
  author = {Moo Jin Kim and Karl Pertsch and Siddharth Karamcheti and Ted Xiao and Ashwin Balakrishna and Suraj Nair and Rafael Rafailov and Ethan P Foster and Pannag R Sanketi and Quan Vuong and Thomas Kollar and Benjamin Burchfiel and Russ Tedrake and Dorsa Sadigh and Sergey Levine and Percy Liang and Chelsea Finn},
  year = {2025},
  url = {https://proceedings.mlr.press/v270/kim25c.html}
}
PreprintKevin Black, Noah Brown, Danny Driess et al.
Introduces a generalist VLA that augments a pretrained vision-language model with a flow-matching action expert for dexterous, high-frequency robot control.
Vision-language-actionFlow matching
Details & sources
Authors: Kevin Black, Noah Brown, Danny Driess, Adnan Esmail, Michael Equi, Chelsea Finn, Niccolo Fusai, Lachy Groom, Karol Hausman, Brian Ichter, Szymon Jakubczak, Tim Jones, Liyiming Ke, Sergey Levine, Adrian Li-Bell, Mohith Mothukuri, Suraj Nair, Karl Pertsch, Lucy Xiaoyang Shi, Laura Smith, James Tanner, Quan Vuong, Anna Walling, Haohuan Wang, Ury Zhilinsky
@inproceedings{pi0-paper,
  title = {π0: A Vision-Language-Action Flow Model for General Robot Control},
  author = {Kevin Black and Noah Brown and Danny Driess and Adnan Esmail and Michael Equi and Chelsea Finn and Niccolo Fusai and Lachy Groom and Karol Hausman and Brian Ichter and Szymon Jakubczak and Tim Jones and Liyiming Ke and Sergey Levine and Adrian Li-Bell and Mohith Mothukuri and Suraj Nair and Karl Pertsch and Lucy Xiaoyang Shi and Laura Smith and James Tanner and Quan Vuong and Anna Walling and Haohuan Wang and Ury Zhilinsky},
  year = {2025},
  booktitle = {RSS},
  url = {https://arxiv.org/abs/2410.24164}
}
@misc{voyager,
  title = {Voyager: An Open-Ended Embodied Agent with Large Language Models},
  author = {Guanzhi Wang and Yuqi Xie and Yunfan Jiang and Ajay Mandlekar and Chaowei Xiao and Yuke Zhu and Linxi Fan and Anima Anandkumar},
  year = {2023},
  url = {https://openreview.net/forum?id=P8E4Br72j3}
}
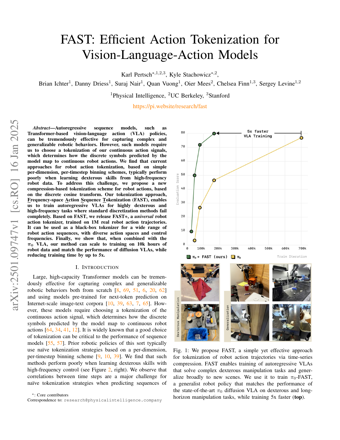
PreprintKarl Pertsch, Kyle Stachowicz, Brian Ichter et al.
Compresses continuous action chunks with a discrete cosine transform and byte-pair encoding, enabling efficient autoregressive VLA training and the π0-FAST policy.
Vision-language-actionAction tokenization
Details & sources
Authors: Karl Pertsch, Kyle Stachowicz, Brian Ichter, Danny Driess, Suraj Nair, Quan Vuong, Oier Mees, Chelsea Finn, Sergey Levine
@inproceedings{pi0-fast,
  title = {FAST: Efficient Action Tokenization for Vision-Language-Action Models},
  author = {Karl Pertsch and Kyle Stachowicz and Brian Ichter and Danny Driess and Suraj Nair and Quan Vuong and Oier Mees and Chelsea Finn and Sergey Levine},
  year = {2025},
  booktitle = {RSS},
  url = {https://arxiv.org/abs/2501.09747}
}
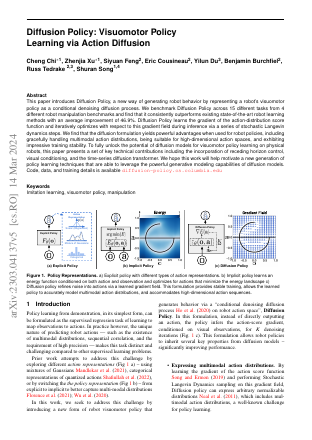
@misc{diffusion-policy,
  title = {Diffusion Policy: Visuomotor Policy Learning via Action Diffusion},
  author = {Cheng Chi and Zhenjia Xu and Siyuan Feng and Eric Cousineau and Yilun Du and Benjamin Burchfiel and Russ Tedrake and Shuran Song},
  year = {2023},
  url = {https://diffusion-policy.cs.columbia.edu/}
}
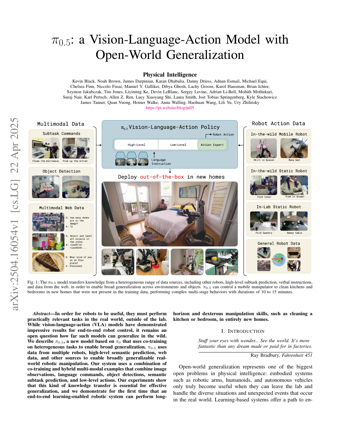
PreprintPhysical Intelligence, Kevin Black, Noah Brown et al.
Extends π0 with heterogeneous co-training across robot actions, semantic subtasks, object grounding, language instructions, and web data for open-world generalization.
Vision-language-actionOpen-world generalization
Details & sources
Authors: Physical Intelligence, Kevin Black, Noah Brown, James Darpinian, Karan Dhabalia, Danny Driess, Adnan Esmail, Michael Equi, Chelsea Finn, Niccolo Fusai, Manuel Y. Galliker, Dibya Ghosh, Lachy Groom, Karol Hausman, Brian Ichter, Szymon Jakubczak, Tim Jones, Liyiming Ke, Devin LeBlanc, Sergey Levine, Adrian Li-Bell, Mohith Mothukuri, Suraj Nair, Karl Pertsch, Allen Z. Ren, Lucy Xiaoyang Shi, Laura Smith, Jost Tobias Springenberg, Kyle Stachowicz, James Tanner, Quan Vuong, Homer Walke, Anna Walling, Haohuan Wang, Lili Yu, Ury Zhilinsky
@inproceedings{pi05,
  title = {π0.5: a Vision-Language-Action Model with Open-World Generalization},
  author = {Physical Intelligence and Kevin Black and Noah Brown and James Darpinian and Karan Dhabalia and Danny Driess and Adnan Esmail and Michael Equi and Chelsea Finn and Niccolo Fusai and Manuel Y. Galliker and Dibya Ghosh and Lachy Groom and Karol Hausman and Brian Ichter and Szymon Jakubczak and Tim Jones and Liyiming Ke and Devin LeBlanc and Sergey Levine and Adrian Li-Bell and Mohith Mothukuri and Suraj Nair and Karl Pertsch and Allen Z. Ren and Lucy Xiaoyang Shi and Laura Smith and Jost Tobias Springenberg and Kyle Stachowicz and James Tanner and Quan Vuong and Homer Walke and Anna Walling and Haohuan Wang and Lili Yu and Ury Zhilinsky},
  year = {2025},
  booktitle = {CoRL},
  url = {https://arxiv.org/abs/2504.16054}
}
Original knowledge-base review label: Spot checks of key claims
BibTeX citation
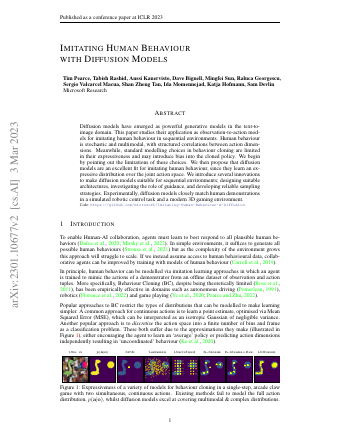
@misc{kb-f02,
  title = {Imitating Human Behaviour with Diffusion Models},
  author = {Tim Pearce and Tabish Rashid and Anssi Kanervisto and Dave Bignell and Mingfei Sun and Raluca Georgescu and Sergio Valcarcel Macua and Shan Zheng Tan and Ida Momennejad and Katja Hofmann and Sam Devlin},
  year = {2023},
  url = {https://arxiv.org/abs/2301.10677}
}
Sources checked 2026-09-14 · Knowledge-base ID F02
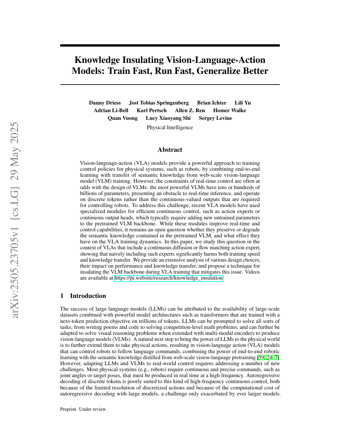
PreprintDanny Driess, Jost Tobias Springenberg, Brian Ichter et al.
Separates continuous-action gradients from the pretrained VLM backbone while using FAST tokens and vision-language co-training to preserve semantic knowledge and speed up learning.
Vision-language-actionKnowledge insulation
Details & sources
Authors: Danny Driess, Jost Tobias Springenberg, Brian Ichter, Lili Yu, Adrian Li-Bell, Karl Pertsch, Allen Z. Ren, Homer Walke, Quan Vuong, Lucy Xiaoyang Shi, Sergey Levine
@inproceedings{pi05-ki,
  title = {Knowledge Insulating Vision-Language-Action Models: Train Fast, Run Fast, Generalize Better},
  author = {Danny Driess and Jost Tobias Springenberg and Brian Ichter and Lili Yu and Adrian Li-Bell and Karl Pertsch and Allen Z. Ren and Homer Walke and Quan Vuong and Lucy Xiaoyang Shi and Sergey Levine},
  year = {2025},
  booktitle = {NeurIPS},
  url = {https://arxiv.org/abs/2505.23705}
}
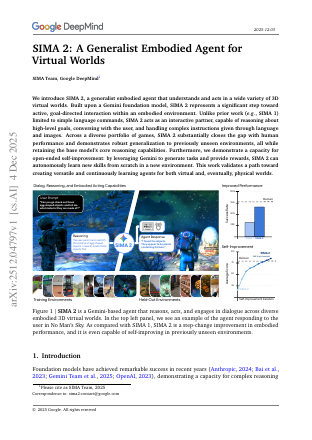
PreprintSIMA team, Adrian Bolton, Alexander Lerchner et al.
Connects Gemini reasoning and interaction to multiple 3D games, studying instruction following, cross-environment generalization, and self-improvement.
Language & actionExploration & skills
Details & sources
Authors: SIMA team, Adrian Bolton, Alexander Lerchner, Alexandra Cordell, Alexandre Moufarek, Andrew Bolt, Andrew Lampinen, Anna Mitenkova, Arne Olav Hallingstad, Bojan Vujatovic, Bonnie Li, Cong Lu, Daan Wierstra, Daniel P. Sawyer, Daniel Slater, David Reichert, Davide Vercelli, Demis Hassabis, Drew A. Hudson, Duncan Williams, Ed Hirst, Fabio Pardo, Felix Hill, Frederic Besse, Hannah Openshaw, Harris Chan, Hubert Soyer, Jane X. Wang, Jeff Clune, John Agapiou, John Reid, Joseph Marino, Junkyung Kim, Karol Gregor, Kaustubh Sridhar, Kay McKinney, Laura Kampis, Lei M. Zhang, Loic Matthey, Luyu Wang, Maria Abi Raad, Maria Loks-Thompson, Martin Engelcke, Matija Kecman, Matthew Jackson, Maxime Gazeau, Ollie Purkiss, Oscar Knagg, Peter Stys, Piermaria Mendolicchio, Raia Hadsell, Rosemary Ke, Ryan Faulkner, Sarah Chakera, Satinder Singh Baveja, Shane Legg, Sheleem Kashem, Tayfun Terzi, Thomas Keck, Tim Harley, Tim Scholtes, Tyson Roberts, Volodymyr Mnih, Yulan Liu, Zhengdong Wang, Zoubin Ghahramani
@misc{sima2,
  title = {SIMA 2: A Generalist Embodied Agent for Virtual Worlds},
  author = {{SIMA team} and Adrian Bolton and Alexander Lerchner and Alexandra Cordell and Alexandre Moufarek and Andrew Bolt and Andrew Lampinen and Anna Mitenkova and Arne Olav Hallingstad and Bojan Vujatovic and Bonnie Li and Cong Lu and Daan Wierstra and Daniel P. Sawyer and Daniel Slater and David Reichert and Davide Vercelli and Demis Hassabis and Drew A. Hudson and Duncan Williams and Ed Hirst and Fabio Pardo and Felix Hill and Frederic Besse and Hannah Openshaw and Harris Chan and Hubert Soyer and Jane X. Wang and Jeff Clune and John Agapiou and John Reid and Joseph Marino and Junkyung Kim and Karol Gregor and Kaustubh Sridhar and Kay McKinney and Laura Kampis and Lei M. Zhang and Loic Matthey and Luyu Wang and Maria Abi Raad and Maria Loks-Thompson and Martin Engelcke and Matija Kecman and Matthew Jackson and Maxime Gazeau and Ollie Purkiss and Oscar Knagg and Peter Stys and Piermaria Mendolicchio and Raia Hadsell and Rosemary Ke and Ryan Faulkner and Sarah Chakera and Satinder Singh Baveja and Shane Legg and Sheleem Kashem and Tayfun Terzi and Thomas Keck and Tim Harley and Tim Scholtes and Tyson Roberts and Volodymyr Mnih and Yulan Liu and Zhengdong Wang and Zoubin Ghahramani},
  year = {2025},
  url = {https://arxiv.org/abs/2512.04797}
}
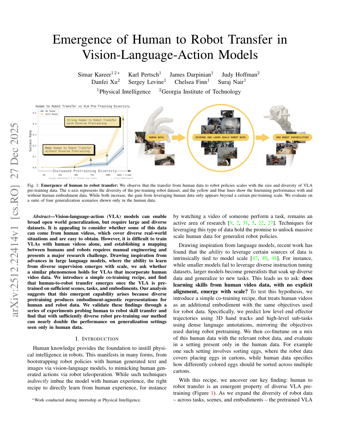
PreprintSimar Kareer, Karl Pertsch, James Darpinian et al.
Shows that human-to-robot transfer emerges with sufficiently diverse VLA pretraining, then adapts π0.5 with egocentric human demonstrations through simple co-training.
Vision-language-actionHuman-to-robot transfer
Details & sources
Authors: Simar Kareer, Karl Pertsch, James Darpinian, Judy Hoffman, Danfei Xu, Sergey Levine, Chelsea Finn, Suraj Nair
@inproceedings{pi05-ego,
  title = {Emergence of Human to Robot Transfer in Vision-Language-Action Models},
  author = {Simar Kareer and Karl Pertsch and James Darpinian and Judy Hoffman and Danfei Xu and Sergey Levine and Chelsea Finn and Suraj Nair},
  year = {2026},
  booktitle = {RSS},
  url = {https://arxiv.org/abs/2512.22414}
}
Original knowledge-base review label: Spot checks of key claims
BibTeX citation
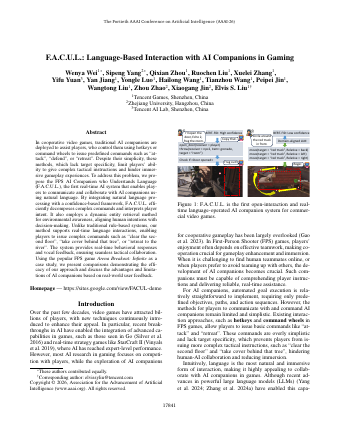
@misc{kb-f07,
  title = {F.A.C.U.L.: Language-Based Interaction with AI Companions in Gaming},
  author = {Wenya Wei and Sipeng Yang and Qixian Zhou and Ruochen Liu and Xuelei Zhang and Yifu Yuan and Yan Jiang and Yongle Luo and Hailong Wang and Tianzhou Wang and Peipei Jin and Wangtong Liu and Zhou Zhao and Xiaogang Jin and Elvis S. Liu},
  year = {2026},
  url = {https://ojs.aaai.org/index.php/AAAI/article/view/38842}
}
Sources checked 2026-09-14 · Knowledge-base ID F07
PreprintPhysical Intelligence, Bo Ai, Ali Amin et al.
Uses diverse multimodal context—language, subgoal images, control labels, speed, and quality—to steer a single generalist policy and recombine skills across robots and tasks.
@misc{pi07,
  title = {π0.7: a Steerable Generalist Robotic Foundation Model with Emergent Capabilities},
  author = {Physical Intelligence and Bo Ai and Ali Amin and Raichelle Aniceto and Ashwin Balakrishna and Greg Balke and Kevin Black and George Bokinsky and Shihao Cao and Thomas Charbonnier and Vedant Choudhary and Foster Collins and Ken Conley and Grace Connors and James Darpinian and Karan Dhabalia and Maitrayee Dhaka and Jared DiCarlo and Danny Driess and Michael Equi and Adnan Esmail and Yunhao Fang and Chelsea Finn and Catherine Glossop and Thomas Godden and Ivan Goryachev and Lachlan Groom and Haroun Habeeb and Hunter Hancock and Karol Hausman and Gashon Hussein and Victor Hwang and Brian Ichter and Connor Jacobsen and Szymon Jakubczak and Rowan Jen and Tim Jones and Gregg Kammerer and Ben Katz and Liyiming Ke and Mairbek Khadikov and Chandra Kuchi and Marinda Lamb and Devin LeBlanc and Brendon LeCount and Sergey Levine and Xinyu Li and Adrian Li-Bell and Vladislav Lialin and Zhonglin Liang and Wallace Lim and Yao Lu and Enyu Luo and Vishnu Mano and Nandan Marwaha and Aikys Mongush and Liam Murphy and Suraj Nair and Tyler Patterson and Karl Pertsch and Allen Z. Ren and Gavin Schelske and Charvi Sharma and Baifeng Shi and Lucy Xiaoyang Shi and Laura Smith and Jost Tobias Springenberg and Kyle Stachowicz and Will Stoeckle and Jiaming Tang and Jimmy Tanner and Shalom Tekeste and Marcel Torne and Kyle Vedder and Quan Vuong and Anna Walling and Haohuan Wang and Jason Wang and XuDong Wang and Chris Whalen and Samuel Whitmore and Blake Williams and Charles Xu and Sukwon Yoo and Lili Yu and Wuming Zhang and Zhuoyang Zhang and Ury Zhilinsky},
  year = {2026},
  url = {https://arxiv.org/abs/2604.15483}
}
PublishedLucy Xiaoyang Shi, Brian Ichter, Michael Robert Equi et al.
Uses a high-level vision-language model to interpret complex instructions and feedback, while a low-level vision-language-action model executes subtasks.
Vision-language-actionPlanning & memory
Details & sources
Authors: Lucy Xiaoyang Shi, Brian Ichter, Michael Robert Equi, Liyiming Ke, Karl Pertsch, Quan Vuong, James Tanner, Anna Walling, Haohuan Wang, Niccolo Fusai, Adrian Li-Bell, Danny Driess, Lachy Groom, Sergey Levine, Chelsea Finn
@misc{hirobot,
  title = {Hi Robot: Open-Ended Instruction Following with Hierarchical Vision-Language-Action Models},
  author = {Lucy Xiaoyang Shi and Brian Ichter and Michael Robert Equi and Liyiming Ke and Karl Pertsch and Quan Vuong and James Tanner and Anna Walling and Haohuan Wang and Niccolo Fusai and Adrian Li-Bell and Danny Driess and Lachy Groom and Sergey Levine and Chelsea Finn},
  year = {2025},
  url = {https://proceedings.mlr.press/v267/shi25d.html}
}
Original knowledge-base review label: Spot checks of key claims
BibTeX citation
@misc{kb-w01,
  title = {Diffusion Models Are Real-Time Game Engines},
  author = {Dani Valevski and Yaniv Leviathan and Moab Arar and Shlomi Fruchter},
  year = {2025},
  url = {https://proceedings.iclr.cc/paper_files/paper/2025/hash/b71ecea210f7159f31e46631fe5c838f-Abstract-Conference.html}
}
Sources checked 2026-09-14 · Knowledge-base ID W01
PreprintPhysical Intelligence, Ali Amin, Raichelle Aniceto et al.
Combines demonstrations, autonomous execution, and human corrections to improve vision-language-action models through advantage-conditioned reinforcement learning.
Vision-language-actionReinforcement learning
Details & sources
Authors: Physical Intelligence, Ali Amin, Raichelle Aniceto, Ashwin Balakrishna, Kevin Black, Ken Conley, Grace Connors, James Darpinian, Karan Dhabalia, Jared DiCarlo, Danny Driess, Michael Equi, Adnan Esmail, Yunhao Fang, Chelsea Finn, Catherine Glossop, Thomas Godden, Ivan Goryachev, Lachy Groom, Hunter Hancock, Karol Hausman, Gashon Hussein, Brian Ichter, Szymon Jakubczak, Rowan Jen, Tim Jones, Ben Katz, Liyiming Ke, Chandra Kuchi, Marinda Lamb, Devin LeBlanc, Sergey Levine, Adrian Li-Bell, Yao Lu, Vishnu Mano, Mohith Mothukuri, Suraj Nair, Karl Pertsch, Allen Z. Ren, Charvi Sharma, Lucy Xiaoyang Shi, Laura Smith, Jost Tobias Springenberg, Kyle Stachowicz, Will Stoeckle, Alex Swerdlow, James Tanner, Marcel Torne, Quan Vuong, Anna Walling, Haohuan Wang, Blake Williams, Sukwon Yoo, Lili Yu, Ury Zhilinsky, Zhiyuan Zhou
@misc{pi-star06,
  title = {π*0.6: a VLA That Learns From Experience},
  author = {{Physical Intelligence} and Ali Amin and Raichelle Aniceto and Ashwin Balakrishna and Kevin Black and Ken Conley and Grace Connors and James Darpinian and Karan Dhabalia and Jared DiCarlo and Danny Driess and Michael Equi and Adnan Esmail and Yunhao Fang and Chelsea Finn and Catherine Glossop and Thomas Godden and Ivan Goryachev and Lachy Groom and Hunter Hancock and Karol Hausman and Gashon Hussein and Brian Ichter and Szymon Jakubczak and Rowan Jen and Tim Jones and Ben Katz and Liyiming Ke and Chandra Kuchi and Marinda Lamb and Devin LeBlanc and Sergey Levine and Adrian Li-Bell and Yao Lu and Vishnu Mano and Mohith Mothukuri and Suraj Nair and Karl Pertsch and Allen Z. Ren and Charvi Sharma and Lucy Xiaoyang Shi and Laura Smith and Jost Tobias Springenberg and Kyle Stachowicz and Will Stoeckle and Alex Swerdlow and James Tanner and Marcel Torne and Quan Vuong and Anna Walling and Haohuan Wang and Blake Williams and Sukwon Yoo and Lili Yu and Ury Zhilinsky and Zhiyuan Zhou},
  year = {2025},
  url = {https://arxiv.org/abs/2511.14759}
}
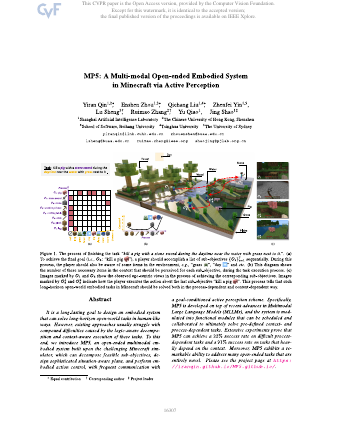
@misc{mp5,
  title = {MP5: A Multi-modal Open-ended Embodied System in Minecraft via Active Perception},
  author = {Yiran Qin and Enshen Zhou and Qichang Liu and Zhenfei Yin and Lu Sheng and Ruimao Zhang and Yu Qiao and Jing Shao},
  year = {2024},
  url = {https://openaccess.thecvf.com/content/CVPR2024/html/Qin_MP5_A_Multi-modal_Open-ended_Embodied_System_in_Minecraft_via_Active_CVPR_2024_paper.html}
}
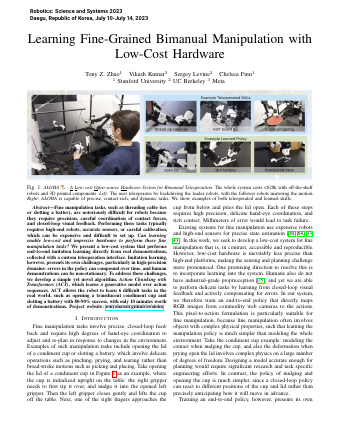
@misc{act,
  title = {Learning Fine-Grained Bimanual Manipulation with Low-Cost Hardware},
  author = {Tony Z. Zhao and Vikash Kumar and Sergey Levine and Chelsea Finn},
  year = {2023},
  url = {https://roboticsproceedings.org/rss19/p016.html}
}
Original knowledge-base review label: Compiled from original notes
BibTeX citation
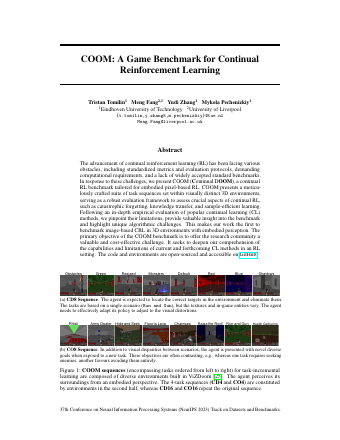
@misc{kb-b01,
  title = {COOM: A Game Benchmark for Continual Reinforcement Learning},
  author = {Tristan Tomilin and Meng Fang and Yudi Zhang and Mykola Pechenizkiy},
  year = {2023},
  url = {https://proceedings.neurips.cc/paper_files/paper/2023/hash/d61d9f4fe4357296cb658795fd7999f0-Abstract-Datasets_and_Benchmarks.html},
  doi = {10.52202/075280-2965}
}
Sources checked 2026-09-14 · Knowledge-base ID B01
Original knowledge-base review label: Compiled from original notes
BibTeX citation
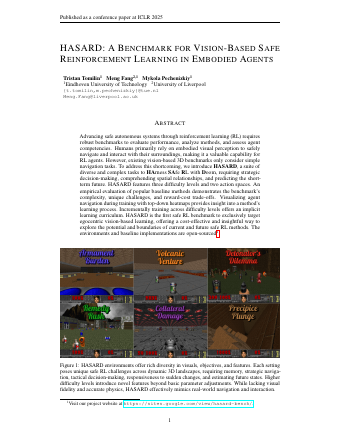
@misc{kb-b02,
  title = {HASARD: A Benchmark for Vision-Based Safe Reinforcement Learning in Embodied Agents},
  author = {Tristan Tomilin and Meng Fang and Mykola Pechenizkiy},
  year = {2025},
  url = {https://proceedings.iclr.cc/paper_files/paper/2025/hash/5ab848771ff8c9c47aac4128e2ef9f4e-Abstract-Conference.html}
}
Sources checked 2026-09-14 · Knowledge-base ID B02
@misc{vpt,
  title = {Video PreTraining (VPT): Learning to Act by Watching Unlabeled Online Videos},
  author = {Bowen Baker and Ilge Akkaya and Peter Zhokov and Joost Huizinga and Jie Tang and Adrien Ecoffet and Brandon Houghton and Raul Sampedro and Jeff Clune},
  year = {2022},
  url = {https://proceedings.neurips.cc/paper_files/paper/2022/hash/9c7008aff45b5d8f0973b23e1a22ada0-Abstract-Conference.html},
  doi = {10.52202/068431-1789}
}
@misc{libero,
  title = {LIBERO: Benchmarking Knowledge Transfer for Lifelong Robot Learning},
  author = {Bo Liu and Yifeng Zhu and Chongkai Gao and Yihao Feng and Qiang Liu and Yuke Zhu and Peter Stone},
  year = {2023},
  url = {https://proceedings.neurips.cc/paper_files/paper/2023/hash/8c3c666820ea055a77726d66fc7d447f-Abstract-Datasets_and_Benchmarks.html},
  doi = {10.52202/075280-1939}
}
Original knowledge-base review label: Compiled from original notes
BibTeX citation
@misc{kb-r01,
  title = {Towards Principled Representation Learning from Videos for Reinforcement Learning},
  author = {Dipendra Kumar Misra and Akanksha Saran and Tengyang Xie and Alex Lamb and John Langford},
  year = {2024},
  url = {https://proceedings.iclr.cc/paper_files/paper/2024/hash/eb60f103645fd14c94826665f8505a6d-Abstract-Conference.html}
}
Sources checked 2026-09-14 · Knowledge-base ID R01
Original knowledge-base review label: Compiled from original notes
BibTeX citation
@misc{kb-r02,
  title = {Catching Two Birds with One Stone: Reward Shaping with Dual Random Networks for Balancing Exploration and Exploitation},
  author = {Haozhe Ma and Fangling Li and Jing Yu Lim and Zhengding Luo and Thanh Vinh Vo and Tze-Yun Leong},
  year = {2025},
  url = {https://proceedings.mlr.press/v267/ma25j.html}
}
Sources checked 2026-09-14 · Knowledge-base ID R02
Original knowledge-base review label: Compiled from original notes
BibTeX citation
@misc{kb-r03,
  title = {Action-Sufficient State Representation Learning for Control with Structural Constraints},
  author = {Biwei Huang and Chaochao Lu and Liu Leqi and Jose Miguel Hernandez-Lobato and Clark Glymour and Bernhard Schölkopf and Kun Zhang},
  year = {2022},
  url = {https://proceedings.mlr.press/v162/huang22f.html}
}
Sources checked 2026-09-14 · Knowledge-base ID R03
Original knowledge-base review label: Compiled from original notes
BibTeX citation
@misc{kb-w02,
  title = {Diffusion for World Modeling: Visual Details Matter in Atari},
  author = {Eloi Alonso and Adam Jelley and Vincent Micheli and Anssi Kanervisto and Amos Storkey and Tim Pearce and François Fleuret},
  year = {2024},
  url = {https://proceedings.neurips.cc/paper_files/paper/2024/hash/6bdde0373d53d4a501249547084bed43-Abstract-Conference.html},
  doi = {10.52202/079017-1873}
}
Sources checked 2026-09-14 · Knowledge-base ID W02
Original knowledge-base review label: Compiled from original notes
BibTeX citation
@misc{kb-w03,
  title = {StateSpaceDiffuser: Bringing Long Context to Diffusion World Models},
  author = {Nedko Savov and Naser Kazemi and Deheng Zhang and Danda Pani Paudel and Xi Wang and Luc V Gool},
  year = {2026},
  url = {https://proceedings.nips.cc/paper_files/paper/2025/hash/63943ee9fe347f3d95892cf87d9a42e6-Abstract-Conference.html},
  doi = {10.52202/085713-2316}
}
Sources checked 2026-09-14 · Knowledge-base ID W03
Original knowledge-base review label: Compiled from original notes
BibTeX citation
@misc{kb-s01,
  title = {EDELINE: Enhancing Memory in Diffusion-based World Models via Linear-Time Sequence Modeling},
  author = {Jia-Hua Lee and Bor-Jiun Lin and Wei-Fang Sun and Chun-Yi Lee},
  year = {2026},
  url = {https://proceedings.neurips.cc/paper_files/paper/2025/hash/97c903fbf21a7d863af2015d8803ca8f-Abstract-Conference.html},
  doi = {10.52202/085713-3526}
}
Sources checked 2026-09-14 · Knowledge-base ID S01
@inproceedings{efficientzero,
  title = {Mastering Atari Games with Limited Data},
  author = {Weirui Ye and Shaohuai Liu and Thanard Kurutach and Pieter Abbeel and Yang Gao},
  booktitle = {NeurIPS 2021},
  year = {2021},
  url = {https://proceedings.neurips.cc/paper/2021/hash/d5eca8dc3820cad9fe56a3bafda65ca1-Abstract.html}
}
Original knowledge-base review label: Compiled from original notes
BibTeX citation
@misc{kb-t01,
  title = {Contextual Similarity Distillation: Ensemble Uncertainties with a Single Model},
  author = {Moritz A. Zanger and Pascal R. Van der Vaart and Wendelin Böhmer and Matthijs T. J. Spaan},
  year = {2025},
  url = {https://iclr.cc/virtual/2026/poster/10008663}
}
Sources checked 2026-09-14 · Knowledge-base ID T01
PublishedScott Reed, Konrad Żołna, Emilio Parisotto et al.
Tokenizes observations and actions from hundreds of tasks so one Transformer can play games, caption images, converse, and control a robot arm.
Generalist agentsMulti-game
Details & sources
Authors: Scott Reed, Konrad Żołna, Emilio Parisotto, Sergio Gómez Colmenarejo, Alexander Novikov, Gabriel Barth-Maron, Mai Giménez, Yury Sulsky, Jackie Kay, Jost Tobias Springenberg, Tom Eccles, Jake Bruce, Ali Razavi, Ashley Edwards, Nicolas Heess, Yutian Chen, Raia Hadsell, Oriol Vinyals, Mahyar Bordbar, Nando de Freitas
@inproceedings{gato,
  title = {A Generalist Agent},
  author = {Scott Reed and Konrad Żołna and Emilio Parisotto and Sergio Gómez Colmenarejo and Alexander Novikov and Gabriel Barth-Maron and Mai Giménez and Yury Sulsky and Jackie Kay and Jost Tobias Springenberg and Tom Eccles and Jake Bruce and Ali Razavi and Ashley Edwards and Nicolas Heess and Yutian Chen and Raia Hadsell and Oriol Vinyals and Mahyar Bordbar and Nando de Freitas},
  booktitle = {TMLR 2022},
  year = {2022},
  url = {https://openreview.net/forum?id=1ikK0kHjvj}
}
Original knowledge-base review label: Compiled from original notes
BibTeX citation
@misc{kb-t02,
  title = {Recurrent Action Transformer with Memory},
  author = {Egor Cherepanov and Alexey Staroverov and Alexey K. Kovalev and Aleksandr I. Panov},
  year = {2023},
  url = {https://iclr.cc/virtual/2026/poster/10007816}
}
Sources checked 2026-09-14 · Knowledge-base ID T02
PublishedAnton Bakhtin, Noam Brown, Emily Dinan et al.
Combines strategic planning with controllable dialogue to negotiate, coordinate, and compete with people in full-press Diplomacy.
Strategy gamesLanguage agents
Details & sources
Authors: Anton Bakhtin, Noam Brown, Emily Dinan, Gabriele Farina, Colin Flaherty, Daniel Fried, Andrew Goff, Jonathan Gray, Hengyuan Hu, Athul Paul Jacob, Mojtaba Komeili, Karthik Konath, Minae Kwon, Adam Lerer, Mike Lewis, Alexander Miller, Sasha Mitts, Adithya Renduchintala, Stephen Roller, Dirk Rowe, Weiyan Shi, Joe Spisak, Alexander Wei, David Wu, Hugh Zhang, Markus Zijlstra
@inproceedings{cicero,
  title = {Human-level play in the game of Diplomacy by combining language models with strategic reasoning},
  author = {Anton Bakhtin and Noam Brown and Emily Dinan and Gabriele Farina and Colin Flaherty and Daniel Fried and Andrew Goff and Jonathan Gray and Hengyuan Hu and Athul Paul Jacob and Mojtaba Komeili and Karthik Konath and Minae Kwon and Adam Lerer and Mike Lewis and Alexander Miller and Sasha Mitts and Adithya Renduchintala and Stephen Roller and Dirk Rowe and Weiyan Shi and Joe Spisak and Alexander Wei and David Wu and Hugh Zhang and Markus Zijlstra},
  booktitle = {Science 2022},
  year = {2022},
  url = {https://doi.org/10.1126/science.ade9097}
}
Original knowledge-base review label: Compiled from original notes
BibTeX citation
@misc{kb-c01,
  title = {Why the Agent Made that Decision: Contrastive Explanation Learning for Reinforcement Learning},
  author = {Rui Zuo and Simon Khan and Zifan Wang and Garrett Ethan Katz and Qinru Qiu},
  year = {2025},
  url = {https://www.ijcai.org/proceedings/2025/74},
  doi = {10.24963/ijcai.2025/74}
}
Sources checked 2026-09-14 · Knowledge-base ID C01
PublishedJulien Pérolat, Bart De Vylder, Daniel Hennes et al.
Uses regularized Nash dynamics and model-free self-play to reach expert-level Stratego without search during play.
Strategy gamesMulti-agent RL
Details & sources
Authors: Julien Pérolat, Bart De Vylder, Daniel Hennes, Eugene Tarassov, Florian Strub, Vincent C. J. de Boer, Paul Müller, Jerome T. Connor, Neil Burch, Thomas Anthony, Stephen McAleer, Romuald Élie, Sarah H. Cen, Zhe Wang, Audrūnas Gruslys, Aleksandra Malysheva, Mina Khan, Sherjil Ozair, Finbarr Timbers, Toby Pohlen, Tom Eccles, Mark Rowland, Marc Lanctot, Jean-Baptiste Lespiau, Bilal Piot, Shayegan Omidshafiei, Edward Lockhart, Laurent Sifre, Nathalie Beauguerlange, Rémi Munos, David Silver, Satinder Singh, Demis Hassabis, Karl Tuyls
@inproceedings{deepnash,
  title = {Mastering the game of Stratego with model-free multiagent reinforcement learning},
  author = {Julien Pérolat and Bart De Vylder and Daniel Hennes and Eugene Tarassov and Florian Strub and Vincent C. J. de Boer and Paul Müller and Jerome T. Connor and Neil Burch and Thomas Anthony and Stephen McAleer and Romuald Élie and Sarah H. Cen and Zhe Wang and Audrūnas Gruslys and Aleksandra Malysheva and Mina Khan and Sherjil Ozair and Finbarr Timbers and Toby Pohlen and Tom Eccles and Mark Rowland and Marc Lanctot and Jean-Baptiste Lespiau and Bilal Piot and Shayegan Omidshafiei and Edward Lockhart and Laurent Sifre and Nathalie Beauguerlange and Rémi Munos and David Silver and Satinder Singh and Demis Hassabis and Karl Tuyls},
  booktitle = {Science 2022},
  year = {2022},
  url = {https://doi.org/10.1126/science.add4679}
}
Original knowledge-base review label: Compiled from original notes
BibTeX citation
@misc{kb-c02,
  title = {Enhancing Robot Program Synthesis Through Environmental Context},
  author = {Tianyi Chen and Qidi Wang and Zhen Dong and Liwei Shen and Xin Peng},
  year = {2023},
  url = {https://proceedings.neurips.cc/paper_files/paper/2023/hash/0c1e94af650f5c74b1f3da467c2308c2-Abstract-Conference.html},
  doi = {10.52202/075280-0171}
}
Sources checked 2026-09-14 · Knowledge-base ID C02
@inproceedings{iris,
  title = {Transformers are Sample-Efficient World Models},
  author = {Vincent Micheli and Eloi Alonso and François Fleuret},
  booktitle = {ICLR 2023},
  year = {2023},
  url = {https://openreview.net/forum?id=vhFu1Acb0xb}
}
Original knowledge-base review label: Compiled from original notes
BibTeX citation
@misc{kb-c03,
  title = {Just Cluster It: An Approach for Exploration in High-Dimensions using Clustering and Pre-Trained Representations},
  author = {Stefan Sylvius Wagner and Stefan Harmeling},
  year = {2024},
  url = {https://proceedings.mlr.press/v235/wagner24a.html}
}
Sources checked 2026-09-14 · Knowledge-base ID C03
PublishedJake Bruce, Michael Dennis, Ashley Edwards et al.
Learns latent actions and video dynamics from unlabeled gameplay, turning a single image or prompt into an interactable generated environment.
Generative environmentsWorld models
Details & sources
Authors: Jake Bruce, Michael Dennis, Ashley Edwards, Jack Parker-Holder, Yuge Shi, Edward Hughes, Matthew Lai, Aditi Mavalankar, Richie Steigerwald, Chris Apps, Yusuf Aytar, Sarah Bechtle, Feryal Behbahani, Stephanie Chan, Nicolas Heess, Lucy González, Simon Osindero, Sherjil Ozair, Scott Reed, Jingwei Zhang, Konrad Żołna, Jeff Clune, Nando de Freitas, Satinder Singh, Tim Rocktäschel
@inproceedings{genie,
  title = {Genie: Generative Interactive Environments},
  author = {Jake Bruce and Michael Dennis and Ashley Edwards and Jack Parker-Holder and Yuge Shi and Edward Hughes and Matthew Lai and Aditi Mavalankar and Richie Steigerwald and Chris Apps and Yusuf Aytar and Sarah Bechtle and Feryal Behbahani and Stephanie Chan and Nicolas Heess and Lucy González and Simon Osindero and Sherjil Ozair and Scott Reed and Jingwei Zhang and Konrad Żołna and Jeff Clune and Nando de Freitas and Satinder Singh and Tim Rocktäschel},
  booktitle = {ICML 2024},
  year = {2024},
  url = {https://proceedings.mlr.press/v235/bruce24a.html}
}
Original knowledge-base review label: Compiled from original notes
BibTeX citation
@misc{kb-c04,
  title = {Exploration via Elliptical Episodic Bonuses},
  author = {Mikael Henaff and Roberta Raileanu and Minqi Jiang and Tim Rocktäschel},
  year = {2022},
  url = {https://proceedings.neurips.cc/paper_files/paper/2022/hash/f4f79698d48bdc1a6dec20583724182b-Abstract-Conference.html},
  doi = {10.52202/068431-2728}
}
Sources checked 2026-09-14 · Knowledge-base ID C04
@inproceedings{bedd,
  title = {BEDD: The MineRL BASALT Evaluation and Demonstrations Dataset for Training and Benchmarking Agents that Solve Fuzzy Tasks},
  author = {Stephanie Milani and Anssi Kanervisto and Karolis Ramanauskas and Sander Schulhoff and Brandon Houghton and Rohin Shah},
  booktitle = {NeurIPS 2023},
  year = {2023},
  url = {https://proceedings.neurips.cc/paper_files/paper/2023/hash/67a6726dcd555b982cabb3446ffac01d-Abstract.html}
}
Original knowledge-base review label: Compiled from original notes
BibTeX citation
@misc{kb-c05,
  title = {Successor Feature Landmarks for Long-Horizon Goal-Conditioned Reinforcement Learning},
  author = {Christopher Hoang and Sungryull Sohn and Jongwook Choi and Wilka Carvalho and Honglak Lee},
  year = {2021},
  url = {https://proceedings.neurips.cc/paper_files/paper/2021/hash/e27c71957d1e6c223e0d48a165da2ee1-Abstract.html}
}
Sources checked 2026-09-14 · Knowledge-base ID C05
Original knowledge-base review label: Compiled from original notes
BibTeX citation
@misc{kb-c06,
  title = {Handling Long and Richly Constrained Tasks through Constrained Hierarchical Reinforcement Learning},
  author = {Yuxiao Lu and Arunesh Sinha and Pradeep Varakantham},
  year = {2024},
  url = {https://ojs.aaai.org/index.php/AAAI/article/view/30132}
}
Sources checked 2026-09-14 · Knowledge-base ID C06
PublishedKuang-Huei Lee, Ofir Nachum, Mengjiao Yang et al.
Scales return-conditioned sequence modeling to one offline Transformer that plays up to 46 Atari games and adapts through fine-tuning.
Offline RLMulti-game
Details & sources
Authors: Kuang-Huei Lee, Ofir Nachum, Mengjiao Yang, Lisa Lee, Daniel Freeman, Winnie Xu, Sergio Guadarrama, Ian Fischer, Eric Jang, Henryk Michalewski, Igor Mordatch
@inproceedings{multi_game_dt,
  title = {Multi-Game Decision Transformers},
  author = {Kuang-Huei Lee and Ofir Nachum and Mengjiao Yang and Lisa Lee and Daniel Freeman and Winnie Xu and Sergio Guadarrama and Ian Fischer and Eric Jang and Henryk Michalewski and Igor Mordatch},
  booktitle = {NeurIPS 2022},
  year = {2022},
  url = {https://proceedings.neurips.cc/paper_files/paper/2022/hash/b2cac94f82928a85055987d9fd44753f-Abstract-Conference.html}
}
Original knowledge-base review label: Compiled from original notes
BibTeX citation
@misc{kb-c08,
  title = {Diverse Projection Ensembles for Distributional Reinforcement Learning},
  author = {Moritz Akiya Zanger and Wendelin Boehmer and Matthijs T. J. Spaan},
  year = {2024},
  url = {https://proceedings.iclr.cc/paper_files/paper/2024/hash/cfea00ddf5a5f514bd3368d639d1933d-Abstract-Conference.html}
}
Sources checked 2026-09-14 · Knowledge-base ID C08
@inproceedings{diplodocus,
  title = {Mastering the Game of No-Press Diplomacy via Human-Regularized Reinforcement Learning and Planning},
  author = {Anton Bakhtin and David J. Wu and Adam Lerer and Jonathan Gray and Athul Paul Jacob and Gabriele Farina and Alexander H. Miller and Noam Brown},
  booktitle = {ICLR 2023},
  year = {2023},
  url = {https://openreview.net/forum?id=F61FwJTZhb}
}
Original knowledge-base review label: Compiled from original notes
BibTeX citation
@misc{kb-c09,
  title = {A Mixture of Surprises for Unsupervised Reinforcement Learning},
  author = {Andrew Zhao and Matthieu Lin and Yangguang Li and Yong-jin Liu and Gao Huang},
  year = {2022},
  url = {https://proceedings.neurips.cc/paper_files/paper/2022/hash/a7667ee5d545a43d2f0fda98863c260e-Abstract-Conference.html},
  doi = {10.52202/068431-1891}
}
Sources checked 2026-09-14 · Knowledge-base ID C09
@inproceedings{decision_transformer,
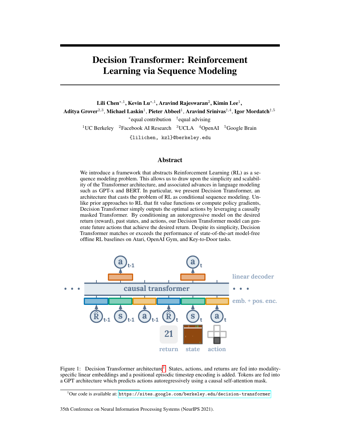
  title = {Decision Transformer: Reinforcement Learning via Sequence Modeling},
  author = {Lili Chen and Kevin Lu and Aravind Rajeswaran and Kimin Lee and Aditya Grover and Misha Laskin and Pieter Abbeel and Aravind Srinivas and Igor Mordatch},
  booktitle = {NeurIPS 2021},
  year = {2021},
  url = {https://proceedings.neurips.cc/paper_files/paper/2021/hash/7f489f642a0ddb10272b5c31057f0663-Abstract.html}
}
@inproceedings{lightzero,
  title = {LightZero: A Unified Benchmark for Monte Carlo Tree Search in General Sequential Decision Scenarios},
  author = {Yazhe Niu and Yuan Pu and Zhenjie Yang and Xueyan Li and Tong Zhou and Jiyuan Ren and Shuai Hu and Hongsheng Li and Yu Liu},
  booktitle = {NeurIPS 2023},
  year = {2023},
  url = {https://proceedings.neurips.cc/paper_files/paper/2023/hash/765043fe026f7d704c96cec027f13843-Abstract-Datasets_and_Benchmarks.html}
}
PublishedZihao Wang, Shaofei Cai, Guanzhou Chen et al.
Connects execution descriptions, failure explanations, and subgoal selection to language planning, revising long-horizon Minecraft plans with feedback.
@misc{deps,
  title = {Describe, Explain, Plan and Select: Interactive Planning with LLMs Enables Open-World Multi-Task Agents},
  author = {Zihao Wang and Shaofei Cai and Guanzhou Chen and Anji Liu and Xiaojian (Shawn) Ma and Yitao Liang},
  year = {2023},
  url = {https://proceedings.neurips.cc/paper_files/paper/2023/hash/6b8dfb8c0c12e6fafc6c256cb08a5ca7-Abstract-Conference.html},
  doi = {10.52202/075280-1480}
}
PublishedMichael Ahn, Anthony Brohan, Noah Brown et al.
Scores language-model plans by the robot skills that are actually feasible, grounding long-horizon instructions in learned affordances.
Language planningAffordances
Details & sources
Authors: Michael Ahn, Anthony Brohan, Noah Brown, Yevgen Chebotar, Omar Cortes, Byron David, Chelsea Finn, Chuyuan Fu, Keerthana Gopalakrishnan, Karol Hausman, Alex Herzog, Daniel Ho, Jasmine Hsu, Julian Ibarz, Brian Ichter, Alex Irpan, Eric Jang, Rosario Jauregui Ruano, Kyle Jeffrey, Sally Jesmonth, Nikhil Joshi, Ryan Julian, Dmitry Kalashnikov, Yuheng Kuang, Kuang-Huei Lee, Sergey Levine, Yao Lu, Linda Luu, Carolina Parada, Peter Pastor, Jornell Quiambao, Kanishka Rao, Jarek Rettinghouse, Diego Reyes, Pierre Sermanet, Nicolas Sievers, Clayton Tan, Alexander Toshev, Vincent Vanhoucke, Fei Xia, Ted Xiao, Peng Xu, Sichun Xu, Mengyuan Yan, Andy Zeng
@inproceedings{saycan,
  title = {Do As I Can, Not As I Say: Grounding Language in Robotic Affordances},
  author = {Michael Ahn and Anthony Brohan and Noah Brown and Yevgen Chebotar and Omar Cortes and Byron David and Chelsea Finn and Chuyuan Fu and Keerthana Gopalakrishnan and Karol Hausman and Alex Herzog and Daniel Ho and Jasmine Hsu and Julian Ibarz and Brian Ichter and Alex Irpan and Eric Jang and Rosario Jauregui Ruano and Kyle Jeffrey and Sally Jesmonth and Nikhil Joshi and Ryan Julian and Dmitry Kalashnikov and Yuheng Kuang and Kuang-Huei Lee and Sergey Levine and Yao Lu and Linda Luu and Carolina Parada and Peter Pastor and Jornell Quiambao and Kanishka Rao and Jarek Rettinghouse and Diego Reyes and Pierre Sermanet and Nicolas Sievers and Clayton Tan and Alexander Toshev and Vincent Vanhoucke and Fei Xia and Ted Xiao and Peng Xu and Sichun Xu and Mengyuan Yan and Andy Zeng},
  booktitle = {CoRL 2022},
  year = {2022},
  url = {https://proceedings.mlr.press/v205/ichter23a.html}
}
PublishedDanny Driess, Fei Xia, Mehdi S. M. Sajjadi et al.
Injects visual and continuous sensor embeddings into a large language model for robot planning, visual reasoning, and transfer across embodiments.
Embodied language modelsMultimodal reasoning
Details & sources
Authors: Danny Driess, Fei Xia, Mehdi S. M. Sajjadi, Corey Lynch, Aakanksha Chowdhery, Brian Ichter, Ayzaan Wahid, Jonathan Tompson, Quan Vuong, Tianhe Yu, Wenlong Huang, Yevgen Chebotar, Pierre Sermanet, Daniel Duckworth, Sergey Levine, Vincent Vanhoucke, Karol Hausman, Marc Toussaint, Klaus Greff, Andy Zeng, Igor Mordatch, Pete Florence
@inproceedings{palm_e,
  title = {PaLM-E: An Embodied Multimodal Language Model},
  author = {Danny Driess and Fei Xia and Mehdi S. M. Sajjadi and Corey Lynch and Aakanksha Chowdhery and Brian Ichter and Ayzaan Wahid and Jonathan Tompson and Quan Vuong and Tianhe Yu and Wenlong Huang and Yevgen Chebotar and Pierre Sermanet and Daniel Duckworth and Sergey Levine and Vincent Vanhoucke and Karol Hausman and Marc Toussaint and Klaus Greff and Andy Zeng and Igor Mordatch and Pete Florence},
  booktitle = {ICML 2023},
  year = {2023},
  url = {https://proceedings.mlr.press/v202/driess23a.html}
}
@inproceedings{rt1,
  title = {RT-1: Robotics Transformer for Real-World Control at Scale},
  author = {Anthony Brohan and Noah Brown and Justice Carbajal and Yevgen Chebotar and Joseph Dabis and Chelsea Finn and Keerthana Gopalakrishnan and Karol Hausman and Alexander Herzog and Jasmine Hsu and Julian Ibarz and Brian Ichter and Alex Irpan and Tomas Jackson and Sally Jesmonth and Nikhil Joshi and Ryan Julian and Dmitry Kalashnikov and Yuheng Kuang and Isabel Leal and Kuang-Huei Lee and Sergey Levine and Yao Lu and Utsav Malla and Deeksha Manjunath and Igor Mordatch and Ofir Nachum and Carolina Parada and Jodilyn Peralta and Emily Perez and Karl Pertsch and Jornell Quiambao and Kanishka Rao and Michael Ryoo and Grecia Salazar and Pannag Sanketi and Kevin Sayed and Jaspiar Singh and Sumedh Sontakke and Austin Stone and Clayton Tan and Huong Tran and Vincent Vanhoucke and Steve Vega and Quan Vuong and Fei Xia and Ted Xiao and Peng Xu and Sichun Xu and Tianhe Yu and Brianna Zitkovich},
  booktitle = {RSS 2023},
  year = {2023},
  url = {https://roboticsproceedings.org/rss19/p025.html}
}
@misc{steve1,
  title = {STEVE-1: A Generative Model for Text-to-Behavior in Minecraft},
  author = {Shalev Lifshitz and Keiran Paster and Harris Chan and Jimmy Ba and Sheila McIlraith},
  year = {2023},
  url = {https://proceedings.neurips.cc/paper_files/paper/2023/hash/dd03f856fc7f2efeec8b1c796284561d-Abstract-Conference.html},
  doi = {10.52202/075280-3064}
}
PublishedYunfan Jiang, Agrim Gupta, Zichen Zhang et al.
Expresses many simulated manipulation tasks as prompts that interleave language, images, and demonstrations, then predicts robot actions autoregressively.
@inproceedings{vima,
  title = {VIMA: General Robot Manipulation with Multimodal Prompts},
  author = {Yunfan Jiang and Agrim Gupta and Zichen Zhang and Guanzhi Wang and Yongqiang Dou and Yanjun Chen and Li Fei-Fei and Anima Anandkumar and Yuke Zhu and Linxi Fan},
  booktitle = {ICML 2023},
  year = {2023},
  url = {https://proceedings.mlr.press/v202/jiang23b.html}
}
@inproceedings{peract,
  title = {Perceiver-Actor: A Multi-Task Transformer for Robotic Manipulation},
  author = {Mohit Shridhar and Lucas Manuelli and Dieter Fox},
  booktitle = {CoRL 2022},
  year = {2022},
  url = {https://proceedings.mlr.press/v205/shridhar23a.html}
}
@inproceedings{r3m,
  title = {R3M: A Universal Visual Representation for Robot Manipulation},
  author = {Suraj Nair and Aravind Rajeswaran and Vikash Kumar and Chelsea Finn and Abhinav Gupta},
  booktitle = {CoRL 2022},
  year = {2022},
  url = {https://proceedings.mlr.press/v205/nair23a.html}
}
@inproceedings{vc1,
  title = {Where are we in the search for an Artificial Visual Cortex for Embodied Intelligence?},
  author = {Arjun Majumdar and Karmesh Yadav and Sergio Arnaud and Jason Ma and Claire Chen and Sneha Silwal and Aryan Jain and Vincent-Pierre Berges and Tingfan Wu and Jay Vakil and Pieter Abbeel and Jitendra Malik and Dhruv Batra and Yixin Lin and Oleksandr Maksymets and Aravind Rajeswaran and Franziska Meier},
  booktitle = {NeurIPS 2023},
  year = {2023},
  url = {https://proceedings.neurips.cc/paper_files/paper/2023/hash/022ca1bed6b574b962c48a2856eb207b-Abstract-Conference.html}
}
PublishedDibya Ghosh, Homer Rich Walke, Karl Pertsch et al.
Pretrains a generalist policy on demonstrations from multiple robots, with language or goal-image conditioning and adaptation to new inputs and action spaces.
Robot learningVision-language-action
Details & sources
Authors: Dibya Ghosh, Homer Rich Walke, Karl Pertsch, Kevin Black, Oier Mees, Sudeep Dasari, Joey Hejna, Tobias Kreiman, Charles Xu, Jianlan Luo, You Liang Tan, Lawrence Yunliang Chen, Quan Vuong, Ted Xiao, Pannag R Sanketi, Dorsa Sadigh, Chelsea Finn, Sergey Levine
@misc{octo,
  title = {Octo: An Open-Source Generalist Robot Policy},
  author = {Dibya Ghosh and Homer Rich Walke and Karl Pertsch and Kevin Black and Oier Mees and Sudeep Dasari and Joey Hejna and Tobias Kreiman and Charles Xu and Jianlan Luo and You Liang Tan and Lawrence Yunliang Chen and Quan Vuong and Ted Xiao and Pannag R Sanketi and Dorsa Sadigh and Chelsea Finn and Sergey Levine},
  year = {2024},
  url = {https://www.roboticsproceedings.org/rss20/p090.html}
}
PublishedKonstantinos Bousmalis, Giulia Vezzani, Dushyant Rao et al.
Trains one goal-conditioned Transformer across robot arms, then uses its own successful rollouts to expand data for new tasks and embodiments.
Generalist policiesSelf-improvement
Details & sources
Authors: Konstantinos Bousmalis, Giulia Vezzani, Dushyant Rao, Coline Devin, Alex Lee, Maria Bauzá, Todor Davchev, Yuxiang Zhou, Agrim Gupta, Akhil Raju, Antoine Laurens, Claudio Fantacci, Valentin Dalibard, Martina Zambelli, Murilo Martins, Rugile Pevceviciute, Michiel Blokzijl, Misha Denil, Nathan Batchelor, Thomas Lampe, Emilio Parisotto, Konrad Żołna, Scott Reed, Sergio Gómez Colmenarejo, Jon Scholz, Abbas Abdolmaleki, Oliver Groth, Jean-Baptiste Regli, Oleg Sushkov, Tom Rothörl, José Enrique Chen, Yusuf Aytar, Dave Barker, Joy Ortiz, Martin Riedmiller, Jost Tobias Springenberg, Raia Hadsell, Francesco Nori, Nicolas Heess
@inproceedings{robocat,
  title = {RoboCat: A Self-Improving Generalist Agent for Robotic Manipulation},
  author = {Konstantinos Bousmalis and Giulia Vezzani and Dushyant Rao and Coline Devin and Alex Lee and Maria Bauzá and Todor Davchev and Yuxiang Zhou and Agrim Gupta and Akhil Raju and Antoine Laurens and Claudio Fantacci and Valentin Dalibard and Martina Zambelli and Murilo Martins and Rugile Pevceviciute and Michiel Blokzijl and Misha Denil and Nathan Batchelor and Thomas Lampe and Emilio Parisotto and Konrad Żołna and Scott Reed and Sergio Gómez Colmenarejo and Jon Scholz and Abbas Abdolmaleki and Oliver Groth and Jean-Baptiste Regli and Oleg Sushkov and Tom Rothörl and José Enrique Chen and Yusuf Aytar and Dave Barker and Joy Ortiz and Martin Riedmiller and Jost Tobias Springenberg and Raia Hadsell and Francesco Nori and Nicolas Heess},
  booktitle = {TMLR 2024},
  year = {2024},
  url = {https://openreview.net/forum?id=vsCpLiIWHu}
}
PublishedBrianna Zitkovich, Tianhe Yu, Sichun Xu et al.
Represents robot actions as tokens and co-trains them with vision-language tasks to study transfer of web knowledge into manipulation.
Vision-language-actionRobot learning
Details & sources
Authors: Brianna Zitkovich, Tianhe Yu, Sichun Xu, Peng Xu, Ted Xiao, Fei Xia, Jialin Wu, Paul Wohlhart, Stefan Welker, Ayzaan Wahid, Quan Vuong, Vincent Vanhoucke, Huong Tran, Radu Soricut, Anikait Singh, Jaspiar Singh, Pierre Sermanet, Pannag R. Sanketi, Grecia Salazar, Michael S. Ryoo, Krista Reymann, Kanishka Rao, Karl Pertsch, Igor Mordatch, Henryk Michalewski, Yao Lu, Sergey Levine, Lisa Lee, Tsang-Wei Edward Lee, Isabel Leal, Yuheng Kuang, Dmitry Kalashnikov, Ryan Julian, Nikhil J. Joshi, Alex Irpan, Brian Ichter, Jasmine Hsu, Alexander Herzog, Karol Hausman, Keerthana Gopalakrishnan, Chuyuan Fu, Pete Florence, Chelsea Finn, Kumar Avinava Dubey, Danny Driess, Tianli Ding, Krzysztof Marcin Choromanski, Xi Chen, Yevgen Chebotar, Justice Carbajal, Noah Brown, Anthony Brohan, Montserrat Gonzalez Arenas, Kehang Han
@misc{rt2,
  title = {RT-2: Vision-Language-Action Models Transfer Web Knowledge to Robotic Control},
  author = {Brianna Zitkovich and Tianhe Yu and Sichun Xu and Peng Xu and Ted Xiao and Fei Xia and Jialin Wu and Paul Wohlhart and Stefan Welker and Ayzaan Wahid and Quan Vuong and Vincent Vanhoucke and Huong Tran and Radu Soricut and Anikait Singh and Jaspiar Singh and Pierre Sermanet and Pannag R. Sanketi and Grecia Salazar and Michael S. Ryoo and Krista Reymann and Kanishka Rao and Karl Pertsch and Igor Mordatch and Henryk Michalewski and Yao Lu and Sergey Levine and Lisa Lee and Tsang-Wei Edward Lee and Isabel Leal and Yuheng Kuang and Dmitry Kalashnikov and Ryan Julian and Nikhil J. Joshi and Alex Irpan and Brian Ichter and Jasmine Hsu and Alexander Herzog and Karol Hausman and Keerthana Gopalakrishnan and Chuyuan Fu and Pete Florence and Chelsea Finn and Kumar Avinava Dubey and Danny Driess and Tianli Ding and Krzysztof Marcin Choromanski and Xi Chen and Yevgen Chebotar and Justice Carbajal and Noah Brown and Anthony Brohan and Montserrat Gonzalez Arenas and Kehang Han},
  year = {2023},
  url = {https://proceedings.mlr.press/v229/zitkovich23a.html}
}
@inproceedings{mobile_aloha,
  title = {Mobile ALOHA: Learning Bimanual Mobile Manipulation using Low-Cost Whole-Body Teleoperation},
  author = {Zipeng Fu and Tony Z. Zhao and Chelsea Finn},
  booktitle = {CoRL 2024},
  year = {2024},
  url = {https://proceedings.mlr.press/v270/fu25b.html}
}
@misc{voxposer,
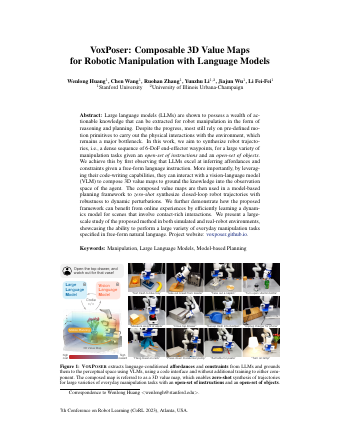
  title = {VoxPoser: Composable 3D Value Maps for Robotic Manipulation with Language Models},
  author = {Wenlong Huang and Chen Wang and Ruohan Zhang and Yunzhu Li and Jiajun Wu and Li Fei-Fei},
  year = {2023},
  url = {https://proceedings.mlr.press/v229/huang23b.html}
}
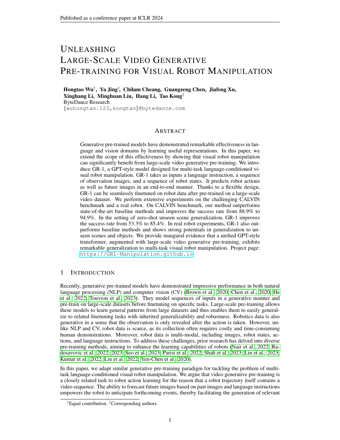
@inproceedings{gr1,
  title = {Unleashing Large-Scale Video Generative Pre-training for Visual Robot Manipulation},
  author = {Hongtao Wu and Ya Jing and Chilam Cheang and Guangzeng Chen and Jiafeng Xu and Xinghang Li and Minghuan Liu and Hang Li and Tao Kong},
  booktitle = {ICLR 2024},
  year = {2024},
  url = {https://proceedings.iclr.cc/paper_files/paper/2024/hash/2c37c5bcef24b9541550261dcd63261b-Abstract-Conference.html}
}
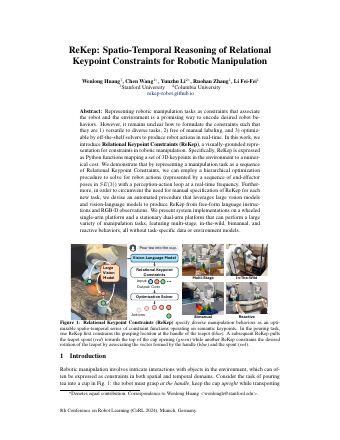
@misc{rekep,
  title = {ReKep: Spatio-Temporal Reasoning of Relational Keypoint Constraints for Robotic Manipulation},
  author = {Wenlong Huang and Chen Wang and Yunzhu Li and Ruohan Zhang and Li Fei-Fei},
  year = {2025},
  url = {https://proceedings.mlr.press/v270/huang25g.html}
}
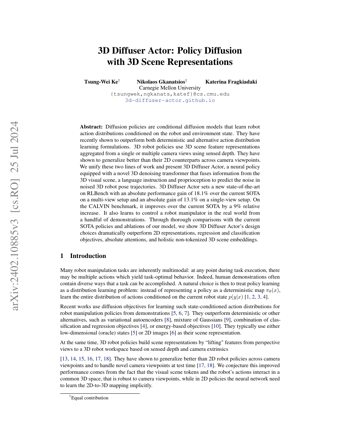
@inproceedings{3d_diffuser_actor,
  title = {3D Diffuser Actor: Policy Diffusion with 3D Scene Representations},
  author = {Tsung-Wei Ke and Nikolaos Gkanatsios and Katerina Fragkiadaki},
  booktitle = {CoRL 2024},
  year = {2024},
  url = {https://proceedings.mlr.press/v270/ke25a.html}
}
@inproceedings{dp3,
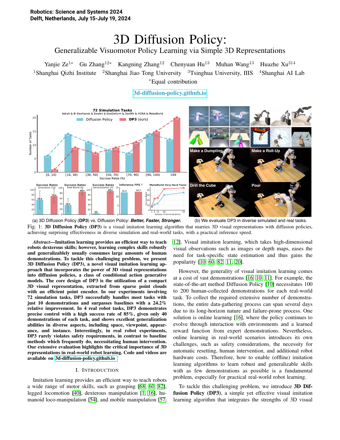
  title = {3D Diffusion Policy: Generalizable Visuomotor Policy Learning via Simple 3D Representations},
  author = {Yanjie Ze and Gu Zhang and Kangning Zhang and Chenyuan Hu and Muhan Wang and Huazhe Xu},
  booktitle = {RSS 2024},
  year = {2024},
  url = {https://www.roboticsproceedings.org/rss20/p067.html}
}
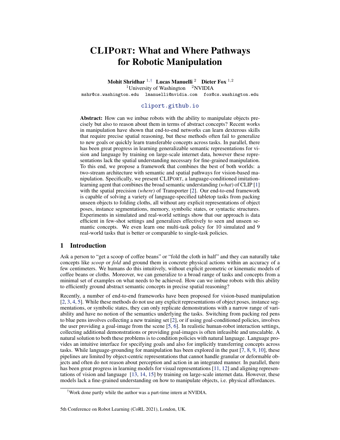
@inproceedings{cliport,
  title = {CLIPort: What and Where Pathways for Robotic Manipulation},
  author = {Mohit Shridhar and Lucas Manuelli and Dieter Fox},
  booktitle = {CoRL 2021},
  year = {2021},
  url = {https://proceedings.mlr.press/v164/shridhar22a.html}
}
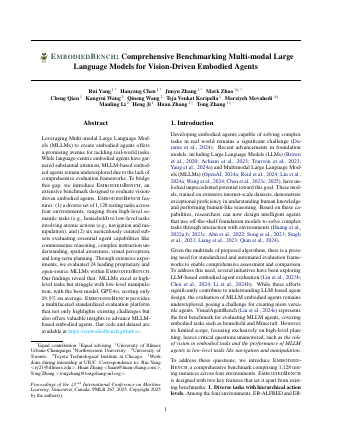
@misc{embodiedbench,
  title = {EmbodiedBench: Comprehensive Benchmarking Multi-modal Large Language Models for Vision-Driven Embodied Agents},
  author = {Rui Yang and Hanyang Chen and Junyu Zhang and Mark Zhao and Cheng Qian and Kangrui Wang and Qineng Wang and Teja Venkat Koripella and Marziyeh Movahedi and Manling Li and Heng Ji and Huan Zhang and Tong Zhang},
  year = {2025},
  url = {https://proceedings.mlr.press/v267/yang25f.html}
}
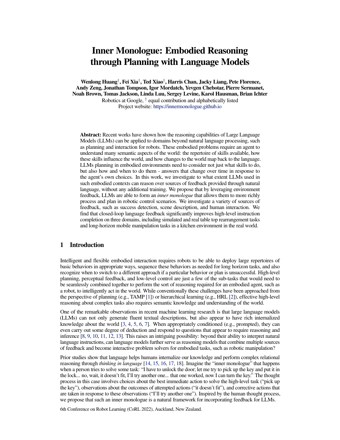
Feeds success detectors, scene descriptions, and human feedback back into an LLM planner so robot plans can react to execution outcomes.
Language planningClosed-loop reasoning
Details & sources
Authors: Wenlong Huang, Fei Xia, Ted Xiao, Harris Chan, Jacky Liang, Pete Florence, Andy Zeng, Jonathan Tompson, Igor Mordatch, Yevgen Chebotar, Pierre Sermanet, Noah Brown, Tomas Jackson, Linda Luu, Sergey Levine, Karol Hausman, Brian Ichter
@inproceedings{inner_monologue,
  title = {Inner Monologue: Embodied Reasoning through Planning with Language Models},
  author = {Wenlong Huang and Fei Xia and Ted Xiao and Harris Chan and Jacky Liang and Pete Florence and Andy Zeng and Jonathan Tompson and Igor Mordatch and Yevgen Chebotar and Pierre Sermanet and Noah Brown and Tomas Jackson and Linda Luu and Sergey Levine and Karol Hausman and Brian Ichter},
  booktitle = {CoRL 2022},
  year = {2022},
  url = {https://proceedings.mlr.press/v205/huang23c.html}
}
@misc{consistency-policy,
  title = {Consistency Policy: Accelerated Visuomotor Policies via Consistency Distillation},
  author = {Aaditya Prasad and Kevin Lin and Jimmy Wu and Linqi Zhou and Jeannette Bohg},
  year = {2024},
  url = {https://www.roboticsproceedings.org/rss20/p071.html}
}
@inproceedings{rt_trajectory,
  title = {RT-Trajectory: Robotic Task Generalization via Hindsight Trajectory Sketches},
  author = {Jiayuan Gu and Sean Kirmani and Paul Wohlhart and Yao Lu and Montserrat Gonzalez Arenas and Kanishka Rao and Wenhao Yu and Chuyuan Fu and Keerthana Gopalakrishnan and Zhuo Xu and Priya Sundaresan and Peng Xu and Hao Su and Karol Hausman and Chelsea Finn and Quan Vuong and Ted Xiao},
  booktitle = {ICLR 2024},
  year = {2024},
  url = {https://proceedings.iclr.cc/paper_files/paper/2024/hash/c383e44d9a878d1982d9abb838bd5d8a-Abstract-Conference.html}
}
@misc{baku,
  title = {BAKU: An Efficient Transformer for Multi-Task Policy Learning},
  author = {Siddhant Haldar and Zhuoran Peng and Lerrel Pinto},
  year = {2024},
  url = {https://proceedings.neurips.cc/paper_files/paper/2024/hash/ff887781480973bd3cb6026feb378d1e-Abstract-Conference.html},
  doi = {10.52202/079017-4484}
}
@inproceedings{code_as_policies,
  title = {Code as Policies: Language Model Programs for Embodied Control},
  author = {Jacky Liang and Wenlong Huang and Fei Xia and Peng Xu and Karol Hausman and Brian Ichter and Pete Florence and Andy Zeng},
  booktitle = {ICRA 2023},
  year = {2023},
  url = {https://doi.org/10.1109/ICRA48891.2023.10160591}
}
@misc{vla-cache,
  title = {VLA-Cache: Efficient Vision-Language-Action Manipulation via Adaptive Token Caching},
  author = {Siyu Xu and Yunke Wang and Chenghao Xia and Dihao Zhu and Tao Huang and Chang Xu},
  year = {2026},
  url = {https://proceedings.neurips.cc/paper_files/paper/2025/hash/f062da1973ac9ac61fc6d44dd7fa309f-Abstract-Conference.html},
  doi = {10.52202/085713-5484}
}
@misc{robochemist,
  title = {RoboChemist: Long-Horizon and Safety-Compliant Robotic Chemical Experimentation},
  author = {Zongzheng Zhang and Chenghao Yue and Haobo Xu and Minwen Liao and Xianglin Qi and Huan-ang Gao and Ziwei Wang and Hao Zhao},
  year = {2025},
  url = {https://proceedings.mlr.press/v305/zhang25i.html}
}
PublishedRoya Firoozi, Johnathan Tucker, Stephen Tian et al.
Reviews how foundation models enter robot perception, planning, and control, with a research agenda spanning data, uncertainty, safety, latency, and reproducibility.
SurveysRobot learning
Details & sources
Authors: Roya Firoozi, Johnathan Tucker, Stephen Tian, Anirudha Majumdar, Jiankai Sun, Weiyu Liu, Yuke Zhu, Shuran Song, Ashish Kapoor, Karol Hausman, Brian Ichter, Danny Driess, Jiajun Wu, Cewu Lu, Mac Schwager
@misc{survey-foundation-robotics,
  title = {Foundation models in robotics: Applications, challenges, and the future},
  author = {Roya Firoozi and Johnathan Tucker and Stephen Tian and Anirudha Majumdar and Jiankai Sun and Weiyu Liu and Yuke Zhu and Shuran Song and Ashish Kapoor and Karol Hausman and Brian Ichter and Danny Driess and Jiajun Wu and Cewu Lu and Mac Schwager},
  year = {2024},
  url = {https://journals.sagepub.com/doi/10.1177/02783649241281508},
  doi = {10.1177/02783649241281508}
}
Publication note: First published online on 2025-11-20; the journal issue is dated 2026.
BibTeX citation
@misc{survey-foundation-manipulation,
  title = {What foundation models can bring for robot learning in manipulation: A survey},
  author = {Dingzhe Li and Yixiang Jin and YuHao Sun and Yong A and Hongze Yu and Jun Shi and Xiaoshuai Hao and Peng Hao and Huaping Liu and Xiang Li and Xinde Li and Fuchun Sun and Jianwei Zhang and Bin Fang},
  year = {2025},
  url = {https://journals.sagepub.com/doi/10.1177/02783649251390579},
  doi = {10.1177/02783649251390579}
}
@misc{minedojo,
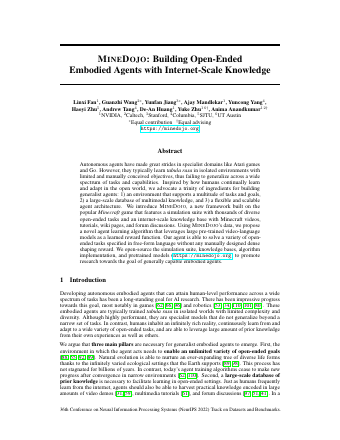
  title = {MineDojo: Building Open-Ended Embodied Agents with Internet-Scale Knowledge},
  author = {Linxi Fan and Guanzhi Wang and Yunfan Jiang and Ajay Mandlekar and Yuncong Yang and Haoyi Zhu and Andrew Tang and De-An Huang and Yuke Zhu and Anima Anandkumar},
  year = {2022},
  url = {https://proceedings.neurips.cc/paper_files/paper/2022/hash/74a67268c5cc5910f64938cac4526a90-Abstract.html},
  doi = {10.52202/068431-1333}
}
@misc{open-x-embodiment,
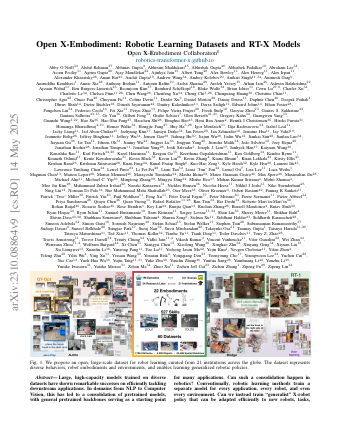
  title = {Open X-Embodiment: Robotic Learning Datasets and RT-X Models},
  author = {Embodiment Collaboration and Abby O'Neill and Abdul Rehman and Abhinav Gupta and Abhiram Maddukuri and Abhishek Gupta and Abhishek Padalkar and Abraham Lee and Acorn Pooley and Agrim Gupta and Ajay Mandlekar and Ajinkya Jain and Albert Tung and Alex Bewley and Alex Herzog and Alex Irpan and Alexander Khazatsky and Anant Rai and Anchit Gupta and Andrew Wang and Andrey Kolobov and Anikait Singh and Animesh Garg and Aniruddha Kembhavi and Annie Xie and Anthony Brohan and Antonin Raffin and Archit Sharma and Arefeh Yavary and Arhan Jain and Ashwin Balakrishna and Ayzaan Wahid and Ben Burgess-Limerick and Beomjoon Kim and Bernhard Schölkopf and Blake Wulfe and Brian Ichter and Cewu Lu and Charles Xu and Charlotte Le and Chelsea Finn and Chen Wang and Chenfeng Xu and Cheng Chi and Chenguang Huang and Christine Chan and Christopher Agia and Chuer Pan and Chuyuan Fu and Coline Devin and Danfei Xu and Daniel Morton and Danny Driess and Daphne Chen and Deepak Pathak and Dhruv Shah and Dieter Büchler and Dinesh Jayaraman and Dmitry Kalashnikov and Dorsa Sadigh and Edward Johns and Ethan Foster and Fangchen Liu and Federico Ceola and Fei Xia and Feiyu Zhao and Felipe Vieira Frujeri and Freek Stulp and Gaoyue Zhou and Gaurav S. Sukhatme and Gautam Salhotra and Ge Yan and Gilbert Feng and Giulio Schiavi and Glen Berseth and Gregory Kahn and Guangwen Yang and Guanzhi Wang and Hao Su and Hao-Shu Fang and Haochen Shi and Henghui Bao and Heni Ben Amor and Henrik I Christensen and Hiroki Furuta and Homanga Bharadhwaj and Homer Walke and Hongjie Fang and Huy Ha and Igor Mordatch and Ilija Radosavovic and Isabel Leal and Jacky Liang and Jad Abou-Chakra and Jaehyung Kim and Jaimyn Drake and Jan Peters and Jan Schneider and Jasmine Hsu and Jay Vakil and Jeannette Bohg and Jeffrey Bingham and Jeffrey Wu and Jensen Gao and Jiaheng Hu and Jiajun Wu and Jialin Wu and Jiankai Sun and Jianlan Luo and Jiayuan Gu and Jie Tan and Jihoon Oh and Jimmy Wu and Jingpei Lu and Jingyun Yang and Jitendra Malik and João Silvério and Joey Hejna and Jonathan Booher and Jonathan Tompson and Jonathan Yang and Jordi Salvador and Joseph J. Lim and Junhyek Han and Kaiyuan Wang and Kanishka Rao and Karl Pertsch and Karol Hausman and Keegan Go and Keerthana Gopalakrishnan and Ken Goldberg and Kendra Byrne and Kenneth Oslund and Kento Kawaharazuka and Kevin Black and Kevin Lin and Kevin Zhang and Kiana Ehsani and Kiran Lekkala and Kirsty Ellis and Krishan Rana and Krishnan Srinivasan and Kuan Fang and Kunal Pratap Singh and Kuo-Hao Zeng and Kyle Hatch and Kyle Hsu and Laurent Itti and Lawrence Yunliang Chen and Lerrel Pinto and Li Fei-Fei and Liam Tan and Linxi "Jim" Fan and Lionel Ott and Lisa Lee and Luca Weihs and Magnum Chen and Marion Lepert and Marius Memmel and Masayoshi Tomizuka and Masha Itkina and Mateo Guaman Castro and Max Spero and Maximilian Du and Michael Ahn and Michael C. Yip and Mingtong Zhang and Mingyu Ding and Minho Heo and Mohan Kumar Srirama and Mohit Sharma and Moo Jin Kim and Muhammad Zubair Irshad and Naoaki Kanazawa and Nicklas Hansen and Nicolas Heess and Nikhil J Joshi and Niko Suenderhauf and Ning Liu and Norman Di Palo and Nur Muhammad Mahi Shafiullah and Oier Mees and Oliver Kroemer and Osbert Bastani and Pannag R Sanketi and Patrick "Tree" Miller and Patrick Yin and Paul Wohlhart and Peng Xu and Peter David Fagan and Peter Mitrano and Pierre Sermanet and Pieter Abbeel and Priya Sundaresan and Qiuyu Chen and Quan Vuong and Rafael Rafailov and Ran Tian and Ria Doshi and Roberto Martín-Martín and Rohan Baijal and Rosario Scalise and Rose Hendrix and Roy Lin and Runjia Qian and Ruohan Zhang and Russell Mendonca and Rutav Shah and Ryan Hoque and Ryan Julian and Samuel Bustamante and Sean Kirmani and Sergey Levine and Shan Lin and Sherry Moore and Shikhar Bahl and Shivin Dass and Shubham Sonawani and Shubham Tulsiani and Shuran Song and Sichun Xu and Siddhant Haldar and Siddharth Karamcheti and Simeon Adebola and Simon Guist and Soroush Nasiriany and Stefan Schaal and Stefan Welker and Stephen Tian and Subramanian Ramamoorthy and Sudeep Dasari and Suneel Belkhale and Sungjae Park and Suraj Nair and Suvir Mirchandani and Takayuki Osa and Tanmay Gupta and Tatsuya Harada and Tatsuya Matsushima and Ted Xiao and Thomas Kollar and Tianhe Yu and Tianli Ding and Todor Davchev and Tony Z. Zhao and Travis Armstrong and Trevor Darrell and Trinity Chung and Vidhi Jain and Vikash Kumar and Vincent Vanhoucke and Vitor Guizilini and Wei Zhan and Wenxuan Zhou and Wolfram Burgard and Xi Chen and Xiangyu Chen and Xiaolong Wang and Xinghao Zhu and Xinyang Geng and Xiyuan Liu and Xu Liangwei and Xuanlin Li and Yansong Pang and Yao Lu and Yecheng Jason Ma and Yejin Kim and Yevgen Chebotar and Yifan Zhou and Yifeng Zhu and Yilin Wu and Ying Xu and Yixuan Wang and Yonatan Bisk and Yongqiang Dou and Yoonyoung Cho and Youngwoon Lee and Yuchen Cui and Yue Cao and Yueh-Hua Wu and Yujin Tang and Yuke Zhu and Yunchu Zhang and Yunfan Jiang and Yunshuang Li and Yunzhu Li and Yusuke Iwasawa and Yutaka Matsuo and Zehan Ma and Zhuo Xu and Zichen Jeff Cui and Zichen Zhang and Zipeng Fu and Zipeng Lin},
  year = {2023},
  url = {https://doi.org/10.1109/ICRA57147.2024.10611477},
  doi = {10.1109/icra57147.2024.10611477}
}
PublishedHomer Rich Walke, Kevin Black, Tony Z. Zhao et al.
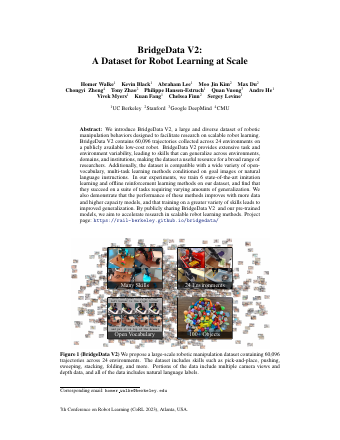
Provides diverse low-cost robot manipulation trajectories across multiple environments for scalable imitation learning and offline reinforcement learning.
DatasetsImitation learning
Details & sources
Authors: Homer Rich Walke, Kevin Black, Tony Z. Zhao, Quan Vuong, Chongyi Zheng, Philippe Hansen-Estruch, Andre Wang He, Vivek Myers, Moo Jin Kim, Max Du, Abraham Lee, Kuan Fang, Chelsea Finn, Sergey Levine
@misc{bridgedata-v2,
  title = {BridgeData V2: A Dataset for Robot Learning at Scale},
  author = {Homer Rich Walke and Kevin Black and Tony Z. Zhao and Quan Vuong and Chongyi Zheng and Philippe Hansen-Estruch and Andre Wang He and Vivek Myers and Moo Jin Kim and Max Du and Abraham Lee and Kuan Fang and Chelsea Finn and Sergey Levine},
  year = {2023},
  url = {https://proceedings.mlr.press/v229/walke23a.html}
}
PublishedAlexander Khazatsky, Karl Pertsch, Suraj Nair et al.
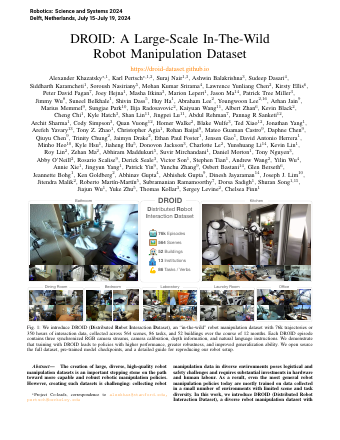
Collects manipulation demonstrations across many scenes and institutions to study learning from diverse real-world experience.
DatasetsImitation learning
Details & sources
Authors: Alexander Khazatsky, Karl Pertsch, Suraj Nair, Ashwin Balakrishna, Sudeep Dasari, Siddharth Karamcheti, Soroush Nasiriany, Mohan Kumar Srirama, Lawrence Yunliang Chen, Kirsty Ellis, Peter David Fagan, Joey Hejna, Masha Itkina, Marion Lepert, Yecheng Jason Ma, Patrick Tree Miller, Jimmy Wu, Suneel Belkhale, Shivin Dass, Huy Ha, Arhan Jain, Abraham Lee, Youngwoon Lee, Marius Memmel, Sungjae Park, Ilija Radosavovic, Kaiyuan Wang, Albert Zhan, Kevin Black, Cheng Chi, Kyle Beltran Hatch, Shan Lin, Jingpei Lu, Jean Mercat, Abdul Rehman, Pannag R Sanketi, Archit Sharma, Cody Simpson, Quan Vuong, Homer Rich Walke, Blake Wulfe, Ted Xiao, Jonathan Heewon Yang, Arefeh Yavary, Tony Z. Zhao, Christopher Agia, Rohan Baijal, Mateo Guaman Castro, Daphne Chen, Qiuyu Chen, Trinity Chung, Jaimyn Drake, Ethan Paul Foster, Jensen Gao, David Antonio Herrera, Minho Heo, Kyle Hsu, Jiaheng Hu, Donovon Jackson, Charlotte Le, Yunshuang Li, Roy Lin, Zehan Ma, Abhiram Maddukuri, Suvir Mirchandani, Daniel Morton, Tony Nguyen, Abigail O'Neill, Rosario Scalise, Derick Seale, Victor Son, Stephen Tian, Emi Tran, Andrew E. Wang, Yilin Wu, Annie Xie, Jingyun Yang, Patrick Yin, Yunchu Zhang, Osbert Bastani, Glen Berseth, Jeannette Bohg, Ken Goldberg, Abhinav Gupta, Abhishek Gupta, Dinesh Jayaraman, Joseph J Lim, Jitendra Malik, Roberto Martín-Martín, Subramanian Ramamoorthy, Dorsa Sadigh, Shuran Song, Jiajun Wu, Michael C. Yip, Yuke Zhu, Thomas Kollar, Sergey Levine, Chelsea Finn
Credit: Alexander Khazatsky and the DROID collaboration
BibTeX citation
@misc{droid,
  title = {DROID: A Large-Scale In-The-Wild Robot Manipulation Dataset},
  author = {Alexander Khazatsky and Karl Pertsch and Suraj Nair and Ashwin Balakrishna and Sudeep Dasari and Siddharth Karamcheti and Soroush Nasiriany and Mohan Kumar Srirama and Lawrence Yunliang Chen and Kirsty Ellis and Peter David Fagan and Joey Hejna and Masha Itkina and Marion Lepert and Yecheng Jason Ma and Patrick Tree Miller and Jimmy Wu and Suneel Belkhale and Shivin Dass and Huy Ha and Arhan Jain and Abraham Lee and Youngwoon Lee and Marius Memmel and Sungjae Park and Ilija Radosavovic and Kaiyuan Wang and Albert Zhan and Kevin Black and Cheng Chi and Kyle Beltran Hatch and Shan Lin and Jingpei Lu and Jean Mercat and Abdul Rehman and Pannag R Sanketi and Archit Sharma and Cody Simpson and Quan Vuong and Homer Rich Walke and Blake Wulfe and Ted Xiao and Jonathan Heewon Yang and Arefeh Yavary and Tony Z. Zhao and Christopher Agia and Rohan Baijal and Mateo Guaman Castro and Daphne Chen and Qiuyu Chen and Trinity Chung and Jaimyn Drake and Ethan Paul Foster and Jensen Gao and David Antonio Herrera and Minho Heo and Kyle Hsu and Jiaheng Hu and Donovon Jackson and Charlotte Le and Yunshuang Li and Roy Lin and Zehan Ma and Abhiram Maddukuri and Suvir Mirchandani and Daniel Morton and Tony Nguyen and Abigail O'Neill and Rosario Scalise and Derick Seale and Victor Son and Stephen Tian and Emi Tran and Andrew E. Wang and Yilin Wu and Annie Xie and Jingyun Yang and Patrick Yin and Yunchu Zhang and Osbert Bastani and Glen Berseth and Jeannette Bohg and Ken Goldberg and Abhinav Gupta and Abhishek Gupta and Dinesh Jayaraman and Joseph J Lim and Jitendra Malik and Roberto Martín-Martín and Subramanian Ramamoorthy and Dorsa Sadigh and Shuran Song and Jiajun Wu and Michael C. Yip and Yuke Zhu and Thomas Kollar and Sergey Levine and Chelsea Finn},
  year = {2024},
  url = {https://www.roboticsproceedings.org/rss20/p120.html}
}
Provides training, inference, and adaptation code for Physical Intelligence robot policies, connecting models to task data.
Vision-language-actionRobot learning
Details & evidence
Environment & tasks: Robot policy training and inference.
Observations & actions: Python, model serving, and dataset configuration.
Scope & limitations: Prepare model weights and hardware dependencies for the chosen release. Do not assume every component of a related paper has been released.
Why included: Standalone open-source tool or environment supporting research and reproduction; excluded from paper-window statistics.
Evidence status: Official repository purpose and interfaces checked; not installed locally.
Provides general-purpose simulation infrastructure for robotics and embodied learning experiments with physical interaction.
Robot learningEnvironment generation
Details & evidence
Environment & tasks: Robot simulation scenes.
Observations & actions: Simulation and control interfaces.
Scope & limitations: Physics, hardware compatibility, and feature support depend on the release. Simulation does not establish validated sim-to-real transfer.
Why included: Standalone open-source tool or environment supporting research and reproduction; excluded from paper-window statistics.
Evidence status: Official repository purpose and interfaces checked; not installed locally.
@misc{minedojo,
  title = {MineDojo: Building Open-Ended Embodied Agents with Internet-Scale Knowledge},
  author = {Linxi Fan and Guanzhi Wang and Yunfan Jiang and Ajay Mandlekar and Yuncong Yang and Haoyi Zhu and Andrew Tang and De-An Huang and Yuke Zhu and Anima Anandkumar},
  year = {2022},
  url = {https://proceedings.neurips.cc/paper_files/paper/2022/hash/74a67268c5cc5910f64938cac4526a90-Abstract.html},
  doi = {10.52202/068431-1333}
}
@misc{open-x-embodiment,
  title = {Open X-Embodiment: Robotic Learning Datasets and RT-X Models},
  author = {Embodiment Collaboration and Abby O'Neill and Abdul Rehman and Abhinav Gupta and Abhiram Maddukuri and Abhishek Gupta and Abhishek Padalkar and Abraham Lee and Acorn Pooley and Agrim Gupta and Ajay Mandlekar and Ajinkya Jain and Albert Tung and Alex Bewley and Alex Herzog and Alex Irpan and Alexander Khazatsky and Anant Rai and Anchit Gupta and Andrew Wang and Andrey Kolobov and Anikait Singh and Animesh Garg and Aniruddha Kembhavi and Annie Xie and Anthony Brohan and Antonin Raffin and Archit Sharma and Arefeh Yavary and Arhan Jain and Ashwin Balakrishna and Ayzaan Wahid and Ben Burgess-Limerick and Beomjoon Kim and Bernhard Schölkopf and Blake Wulfe and Brian Ichter and Cewu Lu and Charles Xu and Charlotte Le and Chelsea Finn and Chen Wang and Chenfeng Xu and Cheng Chi and Chenguang Huang and Christine Chan and Christopher Agia and Chuer Pan and Chuyuan Fu and Coline Devin and Danfei Xu and Daniel Morton and Danny Driess and Daphne Chen and Deepak Pathak and Dhruv Shah and Dieter Büchler and Dinesh Jayaraman and Dmitry Kalashnikov and Dorsa Sadigh and Edward Johns and Ethan Foster and Fangchen Liu and Federico Ceola and Fei Xia and Feiyu Zhao and Felipe Vieira Frujeri and Freek Stulp and Gaoyue Zhou and Gaurav S. Sukhatme and Gautam Salhotra and Ge Yan and Gilbert Feng and Giulio Schiavi and Glen Berseth and Gregory Kahn and Guangwen Yang and Guanzhi Wang and Hao Su and Hao-Shu Fang and Haochen Shi and Henghui Bao and Heni Ben Amor and Henrik I Christensen and Hiroki Furuta and Homanga Bharadhwaj and Homer Walke and Hongjie Fang and Huy Ha and Igor Mordatch and Ilija Radosavovic and Isabel Leal and Jacky Liang and Jad Abou-Chakra and Jaehyung Kim and Jaimyn Drake and Jan Peters and Jan Schneider and Jasmine Hsu and Jay Vakil and Jeannette Bohg and Jeffrey Bingham and Jeffrey Wu and Jensen Gao and Jiaheng Hu and Jiajun Wu and Jialin Wu and Jiankai Sun and Jianlan Luo and Jiayuan Gu and Jie Tan and Jihoon Oh and Jimmy Wu and Jingpei Lu and Jingyun Yang and Jitendra Malik and João Silvério and Joey Hejna and Jonathan Booher and Jonathan Tompson and Jonathan Yang and Jordi Salvador and Joseph J. Lim and Junhyek Han and Kaiyuan Wang and Kanishka Rao and Karl Pertsch and Karol Hausman and Keegan Go and Keerthana Gopalakrishnan and Ken Goldberg and Kendra Byrne and Kenneth Oslund and Kento Kawaharazuka and Kevin Black and Kevin Lin and Kevin Zhang and Kiana Ehsani and Kiran Lekkala and Kirsty Ellis and Krishan Rana and Krishnan Srinivasan and Kuan Fang and Kunal Pratap Singh and Kuo-Hao Zeng and Kyle Hatch and Kyle Hsu and Laurent Itti and Lawrence Yunliang Chen and Lerrel Pinto and Li Fei-Fei and Liam Tan and Linxi "Jim" Fan and Lionel Ott and Lisa Lee and Luca Weihs and Magnum Chen and Marion Lepert and Marius Memmel and Masayoshi Tomizuka and Masha Itkina and Mateo Guaman Castro and Max Spero and Maximilian Du and Michael Ahn and Michael C. Yip and Mingtong Zhang and Mingyu Ding and Minho Heo and Mohan Kumar Srirama and Mohit Sharma and Moo Jin Kim and Muhammad Zubair Irshad and Naoaki Kanazawa and Nicklas Hansen and Nicolas Heess and Nikhil J Joshi and Niko Suenderhauf and Ning Liu and Norman Di Palo and Nur Muhammad Mahi Shafiullah and Oier Mees and Oliver Kroemer and Osbert Bastani and Pannag R Sanketi and Patrick "Tree" Miller and Patrick Yin and Paul Wohlhart and Peng Xu and Peter David Fagan and Peter Mitrano and Pierre Sermanet and Pieter Abbeel and Priya Sundaresan and Qiuyu Chen and Quan Vuong and Rafael Rafailov and Ran Tian and Ria Doshi and Roberto Martín-Martín and Rohan Baijal and Rosario Scalise and Rose Hendrix and Roy Lin and Runjia Qian and Ruohan Zhang and Russell Mendonca and Rutav Shah and Ryan Hoque and Ryan Julian and Samuel Bustamante and Sean Kirmani and Sergey Levine and Shan Lin and Sherry Moore and Shikhar Bahl and Shivin Dass and Shubham Sonawani and Shubham Tulsiani and Shuran Song and Sichun Xu and Siddhant Haldar and Siddharth Karamcheti and Simeon Adebola and Simon Guist and Soroush Nasiriany and Stefan Schaal and Stefan Welker and Stephen Tian and Subramanian Ramamoorthy and Sudeep Dasari and Suneel Belkhale and Sungjae Park and Suraj Nair and Suvir Mirchandani and Takayuki Osa and Tanmay Gupta and Tatsuya Harada and Tatsuya Matsushima and Ted Xiao and Thomas Kollar and Tianhe Yu and Tianli Ding and Todor Davchev and Tony Z. Zhao and Travis Armstrong and Trevor Darrell and Trinity Chung and Vidhi Jain and Vikash Kumar and Vincent Vanhoucke and Vitor Guizilini and Wei Zhan and Wenxuan Zhou and Wolfram Burgard and Xi Chen and Xiangyu Chen and Xiaolong Wang and Xinghao Zhu and Xinyang Geng and Xiyuan Liu and Xu Liangwei and Xuanlin Li and Yansong Pang and Yao Lu and Yecheng Jason Ma and Yejin Kim and Yevgen Chebotar and Yifan Zhou and Yifeng Zhu and Yilin Wu and Ying Xu and Yixuan Wang and Yonatan Bisk and Yongqiang Dou and Yoonyoung Cho and Youngwoon Lee and Yuchen Cui and Yue Cao and Yueh-Hua Wu and Yujin Tang and Yuke Zhu and Yunchu Zhang and Yunfan Jiang and Yunshuang Li and Yunzhu Li and Yusuke Iwasawa and Yutaka Matsuo and Zehan Ma and Zhuo Xu and Zichen Jeff Cui and Zichen Zhang and Zipeng Fu and Zipeng Lin},
  year = {2023},
  url = {https://doi.org/10.1109/ICRA57147.2024.10611477},
  doi = {10.1109/icra57147.2024.10611477}
}
PublishedHomer Rich Walke, Kevin Black, Tony Z. Zhao et al.
Provides diverse low-cost robot manipulation trajectories across multiple environments for scalable imitation learning and offline reinforcement learning.
DatasetsImitation learning
Details & sources
Authors: Homer Rich Walke, Kevin Black, Tony Z. Zhao, Quan Vuong, Chongyi Zheng, Philippe Hansen-Estruch, Andre Wang He, Vivek Myers, Moo Jin Kim, Max Du, Abraham Lee, Kuan Fang, Chelsea Finn, Sergey Levine
@misc{bridgedata-v2,
  title = {BridgeData V2: A Dataset for Robot Learning at Scale},
  author = {Homer Rich Walke and Kevin Black and Tony Z. Zhao and Quan Vuong and Chongyi Zheng and Philippe Hansen-Estruch and Andre Wang He and Vivek Myers and Moo Jin Kim and Max Du and Abraham Lee and Kuan Fang and Chelsea Finn and Sergey Levine},
  year = {2023},
  url = {https://proceedings.mlr.press/v229/walke23a.html}
}
PublishedAlexander Khazatsky, Karl Pertsch, Suraj Nair et al.
Collects manipulation demonstrations across many scenes and institutions to study learning from diverse real-world experience.
DatasetsImitation learning
Details & sources
Authors: Alexander Khazatsky, Karl Pertsch, Suraj Nair, Ashwin Balakrishna, Sudeep Dasari, Siddharth Karamcheti, Soroush Nasiriany, Mohan Kumar Srirama, Lawrence Yunliang Chen, Kirsty Ellis, Peter David Fagan, Joey Hejna, Masha Itkina, Marion Lepert, Yecheng Jason Ma, Patrick Tree Miller, Jimmy Wu, Suneel Belkhale, Shivin Dass, Huy Ha, Arhan Jain, Abraham Lee, Youngwoon Lee, Marius Memmel, Sungjae Park, Ilija Radosavovic, Kaiyuan Wang, Albert Zhan, Kevin Black, Cheng Chi, Kyle Beltran Hatch, Shan Lin, Jingpei Lu, Jean Mercat, Abdul Rehman, Pannag R Sanketi, Archit Sharma, Cody Simpson, Quan Vuong, Homer Rich Walke, Blake Wulfe, Ted Xiao, Jonathan Heewon Yang, Arefeh Yavary, Tony Z. Zhao, Christopher Agia, Rohan Baijal, Mateo Guaman Castro, Daphne Chen, Qiuyu Chen, Trinity Chung, Jaimyn Drake, Ethan Paul Foster, Jensen Gao, David Antonio Herrera, Minho Heo, Kyle Hsu, Jiaheng Hu, Donovon Jackson, Charlotte Le, Yunshuang Li, Roy Lin, Zehan Ma, Abhiram Maddukuri, Suvir Mirchandani, Daniel Morton, Tony Nguyen, Abigail O'Neill, Rosario Scalise, Derick Seale, Victor Son, Stephen Tian, Emi Tran, Andrew E. Wang, Yilin Wu, Annie Xie, Jingyun Yang, Patrick Yin, Yunchu Zhang, Osbert Bastani, Glen Berseth, Jeannette Bohg, Ken Goldberg, Abhinav Gupta, Abhishek Gupta, Dinesh Jayaraman, Joseph J Lim, Jitendra Malik, Roberto Martín-Martín, Subramanian Ramamoorthy, Dorsa Sadigh, Shuran Song, Jiajun Wu, Michael C. Yip, Yuke Zhu, Thomas Kollar, Sergey Levine, Chelsea Finn
Credit: Alexander Khazatsky and the DROID collaboration
BibTeX citation
@misc{droid,
  title = {DROID: A Large-Scale In-The-Wild Robot Manipulation Dataset},
  author = {Alexander Khazatsky and Karl Pertsch and Suraj Nair and Ashwin Balakrishna and Sudeep Dasari and Siddharth Karamcheti and Soroush Nasiriany and Mohan Kumar Srirama and Lawrence Yunliang Chen and Kirsty Ellis and Peter David Fagan and Joey Hejna and Masha Itkina and Marion Lepert and Yecheng Jason Ma and Patrick Tree Miller and Jimmy Wu and Suneel Belkhale and Shivin Dass and Huy Ha and Arhan Jain and Abraham Lee and Youngwoon Lee and Marius Memmel and Sungjae Park and Ilija Radosavovic and Kaiyuan Wang and Albert Zhan and Kevin Black and Cheng Chi and Kyle Beltran Hatch and Shan Lin and Jingpei Lu and Jean Mercat and Abdul Rehman and Pannag R Sanketi and Archit Sharma and Cody Simpson and Quan Vuong and Homer Rich Walke and Blake Wulfe and Ted Xiao and Jonathan Heewon Yang and Arefeh Yavary and Tony Z. Zhao and Christopher Agia and Rohan Baijal and Mateo Guaman Castro and Daphne Chen and Qiuyu Chen and Trinity Chung and Jaimyn Drake and Ethan Paul Foster and Jensen Gao and David Antonio Herrera and Minho Heo and Kyle Hsu and Jiaheng Hu and Donovon Jackson and Charlotte Le and Yunshuang Li and Roy Lin and Zehan Ma and Abhiram Maddukuri and Suvir Mirchandani and Daniel Morton and Tony Nguyen and Abigail O'Neill and Rosario Scalise and Derick Seale and Victor Son and Stephen Tian and Emi Tran and Andrew E. Wang and Yilin Wu and Annie Xie and Jingyun Yang and Patrick Yin and Yunchu Zhang and Osbert Bastani and Glen Berseth and Jeannette Bohg and Ken Goldberg and Abhinav Gupta and Abhishek Gupta and Dinesh Jayaraman and Joseph J Lim and Jitendra Malik and Roberto Martín-Martín and Subramanian Ramamoorthy and Dorsa Sadigh and Shuran Song and Jiajun Wu and Michael C. Yip and Yuke Zhu and Thomas Kollar and Sergey Levine and Chelsea Finn},
  year = {2024},
  url = {https://www.roboticsproceedings.org/rss20/p120.html}
}
Original knowledge-base review label: Compiled from original notes
BibTeX citation
@misc{kb-b01,
  title = {COOM: A Game Benchmark for Continual Reinforcement Learning},
  author = {Tristan Tomilin and Meng Fang and Yudi Zhang and Mykola Pechenizkiy},
  year = {2023},
  url = {https://proceedings.neurips.cc/paper_files/paper/2023/hash/d61d9f4fe4357296cb658795fd7999f0-Abstract-Datasets_and_Benchmarks.html},
  doi = {10.52202/075280-2965}
}
Sources checked 2026-09-14 · Knowledge-base ID B01
Original knowledge-base review label: Compiled from original notes
BibTeX citation
@misc{kb-b02,
  title = {HASARD: A Benchmark for Vision-Based Safe Reinforcement Learning in Embodied Agents},
  author = {Tristan Tomilin and Meng Fang and Mykola Pechenizkiy},
  year = {2025},
  url = {https://proceedings.iclr.cc/paper_files/paper/2025/hash/5ab848771ff8c9c47aac4128e2ef9f4e-Abstract-Conference.html}
}
Sources checked 2026-09-14 · Knowledge-base ID B02
@misc{libero,
  title = {LIBERO: Benchmarking Knowledge Transfer for Lifelong Robot Learning},
  author = {Bo Liu and Yifeng Zhu and Chongkai Gao and Yihao Feng and Qiang Liu and Yuke Zhu and Peter Stone},
  year = {2023},
  url = {https://proceedings.neurips.cc/paper_files/paper/2023/hash/8c3c666820ea055a77726d66fc7d447f-Abstract-Datasets_and_Benchmarks.html},
  doi = {10.52202/075280-1939}
}
@misc{embodiedbench,
  title = {EmbodiedBench: Comprehensive Benchmarking Multi-modal Large Language Models for Vision-Driven Embodied Agents},
  author = {Rui Yang and Hanyang Chen and Junyu Zhang and Mark Zhao and Cheng Qian and Kangrui Wang and Qineng Wang and Teja Venkat Koripella and Marziyeh Movahedi and Manling Li and Heng Ji and Huan Zhang and Tong Zhang},
  year = {2025},
  url = {https://proceedings.mlr.press/v267/yang25f.html}
}
Provides configurable first-person visual tasks based on DOOM for navigation, survival, and shooting research.
BenchmarksReinforcement learning
Details & evidence
Environment & tasks: DOOM.
Observations & actions: Visual observations, game variables, and discrete actions.
Scope & limitations: Specify access to game variables, frame skipping, and the action set. The underlying environment is not subject to the paper publication window.
Why included: Standalone open-source tool or environment supporting research and reproduction; excluded from paper-window statistics.
Evidence status: Official repository purpose and interfaces checked; not installed locally.
Observations & actions: Simulated observations, actions, and skill tasks.
Scope & limitations: Specify the environment version, robot, control mode, and training data. Simulation throughput is not real-world control performance.
Why included: Standalone open-source tool or environment supporting research and reproduction; excluded from paper-window statistics.
Evidence status: Official repository purpose and interfaces checked; not installed locally.
Interface: JavaScript skill code, game state, and execution feedback.
Playback & limitations: Programmatic skill execution with Mineflayer; the authors render demonstrations from recorded gameplay, which is not a record of pixel-only control.
Evidence: Original project video and source page checked. Qualitative, author-reported evidence; not independently reproduced.
Interface: JavaScript skill code, game state, and execution feedback.
Playback & limitations: A selected skill demonstration, not evidence of success on every task. The recording viewpoint is distinct from the programmatic observation interface.
Evidence: Original project video and source page checked. Qualitative, author-reported evidence; not independently reproduced.
Interface: Past game frames and player actions condition diffusion-based next-frame prediction. PPO primarily collects training trajectories.
Playback & limitations: This demonstrates frame generation conditioned on actions. It is not an autonomous game-playing policy or a measured combat result.
Evidence: Original project video and source page checked. Qualitative, author-reported evidence; not independently reproduced.
Setting: Atari; Counter-Strike: Global Offensive, Dust II.
Interface: Human CS:GO frames and actions feed low-resolution dynamics and super-resolution generation. The shooter extension does not train an RL policy.
Playback & limitations: Keep the CS:GO generation extension separate from Atari policy-learning results. Visual continuity is not a combat success metric.
Evidence: Original project video and source page checked. Qualitative, author-reported evidence; not independently reproduced.
Interface: RGB images and language map to robot actions.
Playback & limitations: The source clip is labeled 1.5× speed. This selected qualitative rollout is not a control-frequency measurement or an aggregate success rate.
Evidence: Original project video and source page checked. Qualitative, author-reported evidence; not independently reproduced.
Interface: Images and joint observations map to action chunks.
Playback & limitations: The source labels this a real-time learned-policy rollout, separate from its teleoperation examples. This selected task does not establish arbitrary dexterity.
Evidence: Original project video and source page checked. Qualitative, author-reported evidence; not independently reproduced.
Setting: A real kitchen with a mobile dual-arm ALOHA platform.
Interface: Camera observations drive learned base, arm, and gripper actions cloned from whole-body demonstrations.
Playback & limitations: A selected successful rollout does not report the task success distribution or cover changes outside the evaluated kitchen setup.
Evidence: Original project video and source page checked. Qualitative, author-reported evidence; not independently reproduced.
Setting: Real tabletop articulated-object manipulation.
Interface: Language, image history, and robot state tokens condition action and future-image predictions.
Playback & limitations: This is one author-selected rollout; it does not isolate how much performance comes from video pretraining versus robot fine-tuning.
Evidence: Original project video and source page checked. Qualitative, author-reported evidence; not independently reproduced.
Interface: RGB observations and language condition pick-and-place predictions.
Playback & limitations: The action abstraction is tailored to tabletop pick-and-place and cannot represent every deformation or continuous force profile.
Evidence: Original project video and source page checked. Qualitative, author-reported evidence; not independently reproduced.
A restricted request or timeout can reflect publisher protections or a temporary outage. Links stay in the collection until reviewed. A “missing” result requires a 404 or 410 response to a GET request.
Moved the repository and website to LAMDA-NeSy while preserving the project history, contributors, issues, and community stars. Future releases and contributions now live under the organization.
Collection update
The complete Physical Intelligence π model line
Added the full π model progression from π0 and π0-FAST through π0.5, knowledge insulation, human-to-robot transfer, π*0.6, and π0.7, with official papers, project pages, affiliations, previews, and available metrics.
Collection update
28 representative papers and 9 original demos
Expanded game research across Atari, world models, generalist agents, Minecraft evaluation, and strategic multi-agent play; expanded embodied research across language planning, robot Transformers, visual pretraining, 3D diffusion policies, and mobile bimanual systems. Every new paper links to a verified formal publication record, and every new video comes from its original project page.
Community update
A warmer welcome and a shared future vision
Expanded the repository welcome, community contribution paths, and long-term vision, with a new illustration connecting virtual experience, shared agent methods, and physical-world learning.
Website update
Clearer records, a lighter reading experience
Labeled source dates, consistent category counts, separate date and venue-year sorting, and collection history. Weekly source-link checks and citation/star refreshes keep existing records current.
Collection launch
The first curated collection
72 selected resources across game and embodied research, including 49 papers and 8 original-source video demos. Eight candidate papers remain separate. Existing records use this date as the collection-history baseline.
About the collection
A research index connecting game agents and embodied intelligence. Game research starts from the supplied Game Agent knowledge base; robotics and additional game resources come from official proceedings, research reports, and project repositories.
The organization and website layout are inspired by Awesome Robot Use Agent. This collection has its own scope, categories, and resource summaries.
Snapshot · 2026-09-14
115 unique curated resources: 6 articles, 83 papers, 5 standalone projects, 4 datasets, 8 benchmarks or environments, and 17 video demonstrations. Dataset and benchmark papers appear in multiple views, so these counts overlap. 8 candidates are listed separately.
Selection criteria
Track
Publication window
Selection basis
Leading conferences & journals
14 Sep 2021 – 14 Sep 2026
Relevant main-conference papers and journal articles with official publication records. Priority venues include NeurIPS, ICLR, ICML, CVPR, ICCV, ECCV, AAAI, IJCAI, RSS, CoRL, ICRA, IROS, Nature, Science, T-RO, IJRR, TPAMI, JMLR, and TMLR.
Selected arXiv research
14 Sep 2025 – 14 Sep 2026
First submission date, with a specific editorial rationale and supporting sources. Evidence can include systematic evaluations, released models or environments, and substantial research reports. No citation ranking is claimed.
Tools & environments
Reviewed for current research use
Standalone infrastructure is assessed by purpose, interface, and setup requirements. The paper publication window does not apply.
This venue list reflects the collection's subject-specific editorial policy, rather than a single official ranking. Workshops and unconfirmed submissions are distinguished from main-conference publications. See the full collection policy.
Sources and verification
The source table contained 106 rows. Removing 19 untitled rows and merging 4 duplicates produced 83 distinct titled leads. Historical counts on the knowledge-base homepage were not used for this snapshot.
Checks primarily cover bibliographic records, project descriptions, and abstracts. Original knowledge-base review labels are retained as source claims, translated into English. They do not represent a fresh full-text review or independent experiment reproduction.
Paper rows include full titles, credited authors, source dates, PDF links, and original first-page previews where available. Dates are labeled Published, Preprint, or Indexed according to their source. Venue / release year and Source date are separate sort options. Year filters use the conference or journal year for papers; proceedings dates can differ. Recently added and Recently revised refer to the collection, not to publication. Expand Details & sources for the complete author list and a BibTeX citation.
Citations come from the linked OpenAlex or Crossref record, and stars from the linked GitHub repository. Each count carries its retrieval date. Counts are cached snapshots and can differ across paper versions and databases. Missing resource links appear as muted, non-clickable icons; unavailable citation and star counts show an em dash. See metadata sources and maintenance.
Comparing game and embodied agents
Dimension
Game research
Embodied research
Environment & task
Game, map, mode, and task scope
Hardware, scene, objects, and manipulation tasks
Observation access
Pixels, audio, text, or engine state
Images, depth, touch, and proprioception
Action abstraction
Keyboard/mouse, program APIs, or skills
Joints, end-effector poses, or navigation/manipulation skills
Data & learning
Player traces, online interaction, video pretraining
Demonstrations, teleoperation, simulation, real interaction
Execution constraints
Decision latency, frame rate, paused execution
Control frequency, collisions, hardware limits
Evaluation
Map splits, task metrics, samples, and seeds
Task success, generalization, and human intervention
Shared methods do not by themselves establish transfer between domains. Frame generation, game navigation, robot planning, and physical execution retain their respective evidence boundaries.
Video demonstrations
The video gallery embeds original research-team videos, with source links, credits, and related work. Game control, generated frames, real robots, and simulation are labeled separately. Selected clips illustrate behavior; they do not replace benchmark evaluations. Videos load as you approach them and play only when requested. If an external host is unavailable, use the source link on the card.
Maintenance and contributions
The README and website share the same catalogue. New additions are manually curated. Weekly maintenance checks existing source links and refreshes verified statistics. See What’s new for recent additions, the update log, and maintenance reports. Additions should include official sources and satisfy the selection criteria. Read the contribution guide or visit the GitHub repository.